jev-aita
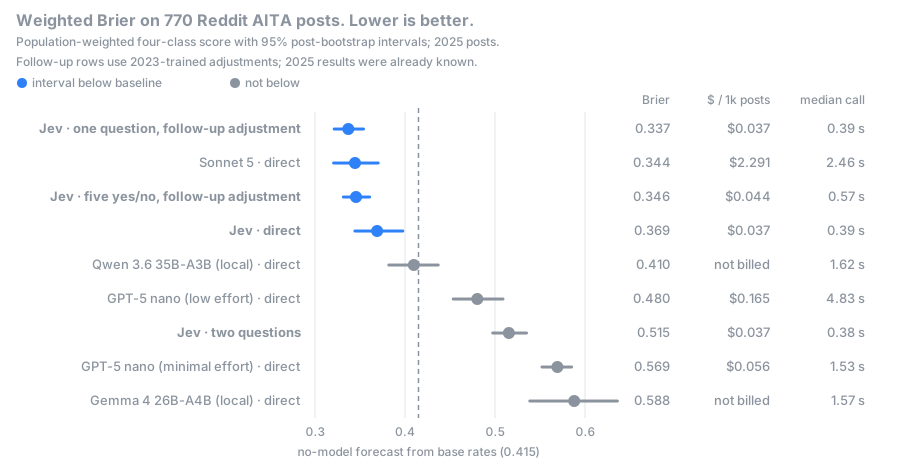
Benchmark of TypeSafe's Jev against Sonnet 5, GPT-5 nano and local LLMs on 770 Reddit AITA verdicts: Brier scores, latency and cost
How it uses Jev
Jev vs. LLMs on Reddit's "Am I the Asshole?"
Highlights
- Who is actually right. Only how well each model predicts Reddit's verdict
- Label-only use. Every model had to give four probabilities, Jev natively
- Full-size local models. Qwen and Gemma ran as 4-bit builds with reasoning
- Language
- Python 100%
- Last activity
- Sep 2026
- Added
- 2026-09-24
- Stars at snapshot
- 2
- Status
- Community listing
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.