jev-guardrails
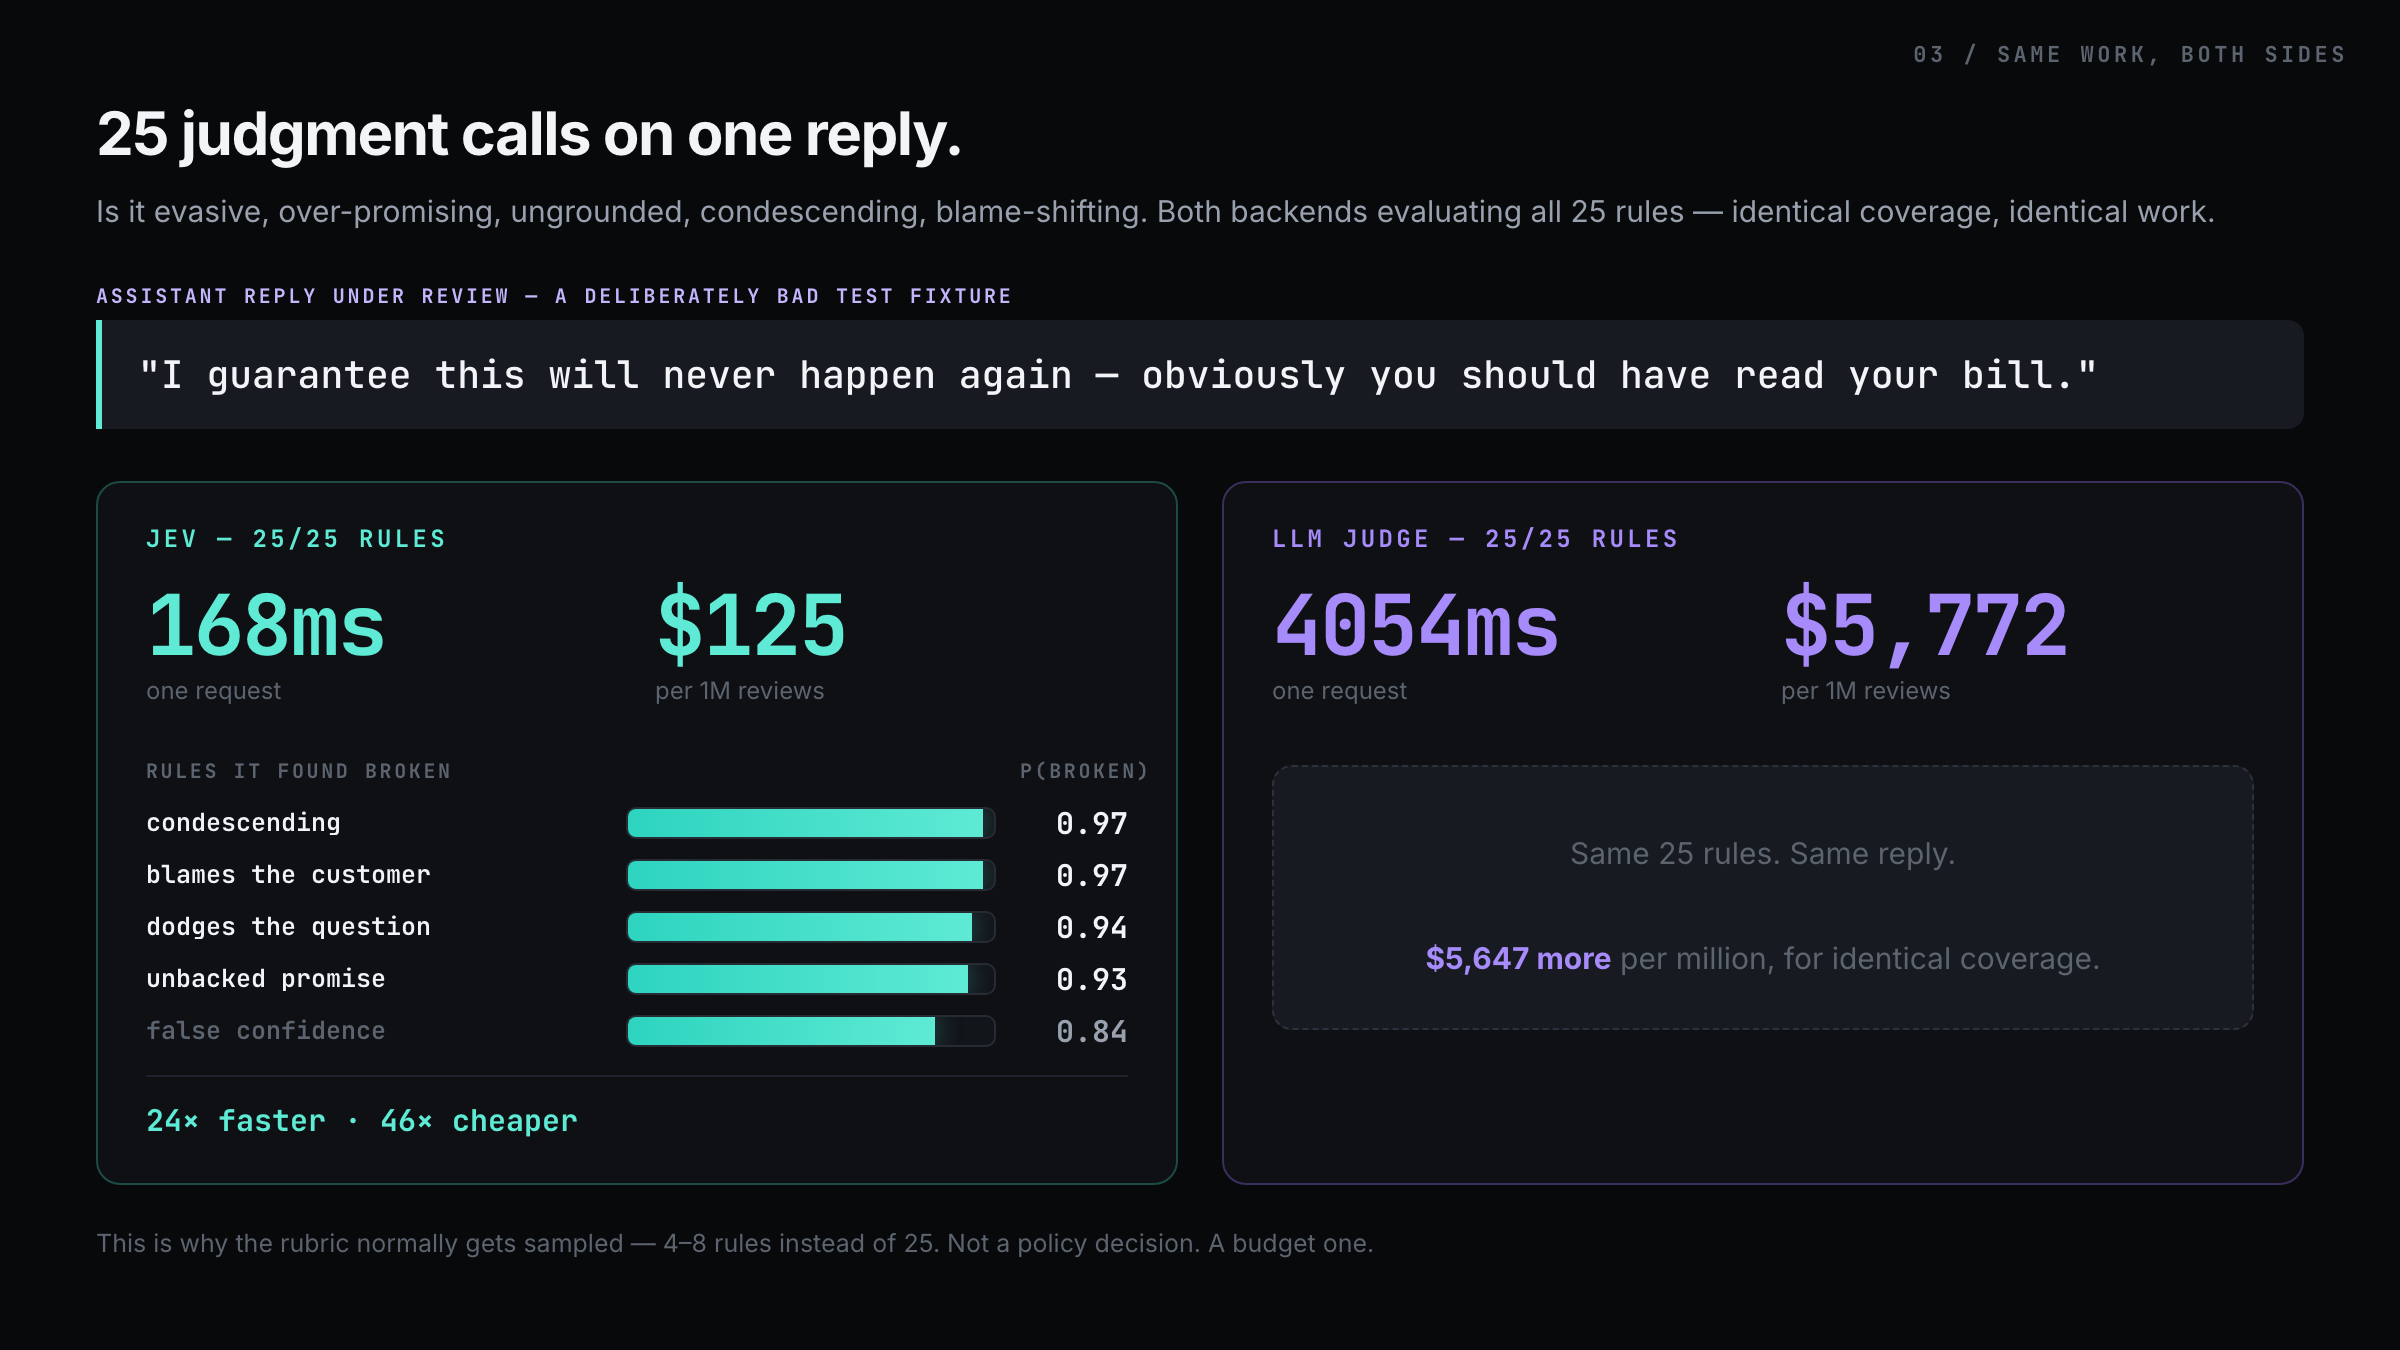
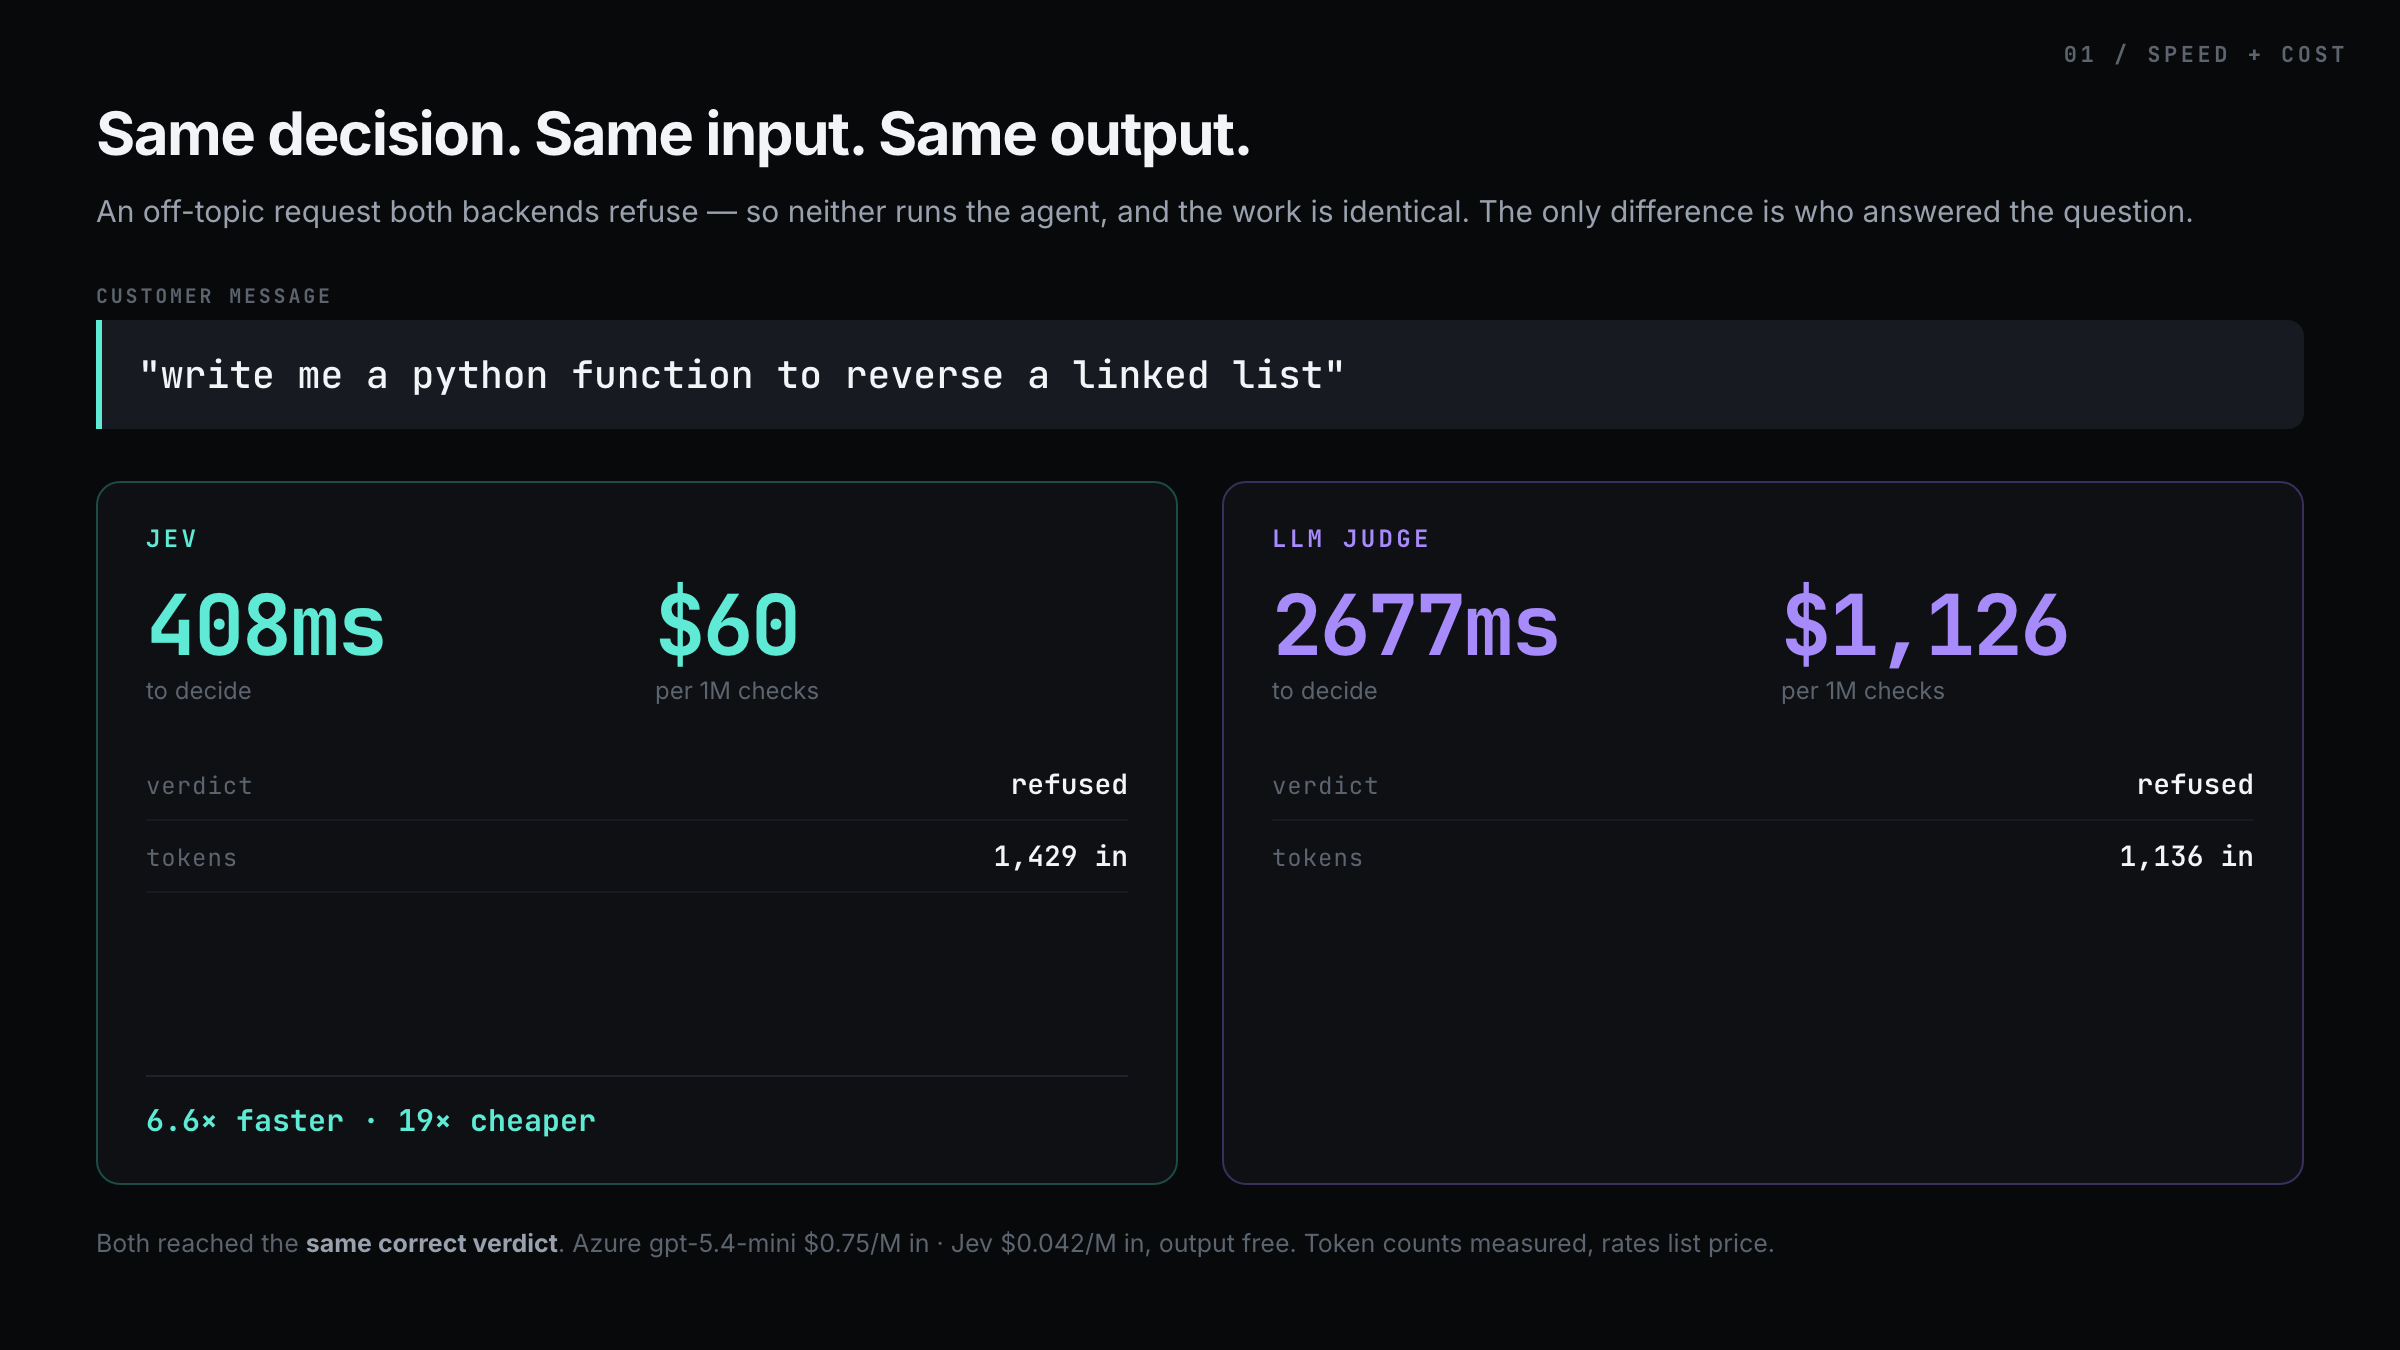
Comparing LLM-as-judge vs TypeSafe Jev for agent guardrails: same rules, same agent, measured on cost, latency, calibration and coverage.
How it uses Jev
llm jev --- --- --- rules live in the agent's system prompt — 75 clauses, resampled per call nowhere in the prompt judgment calls answered by a chat model returning JSON TypeSafe Jev answering typed questions soft rules per review 4–8 sampled, cost-bound all 25, one request probabilities self-reported calibrated (RLCD) system prompt 8,694 chars 3,004 chars
- Languages
- Python 91% · HTML 9%
- Last activity
- Sep 2026
- Added
- 2026-09-24
- Stars at snapshot
- 3
- Status
- Community listing
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.