jevbench (dhruvmehra)
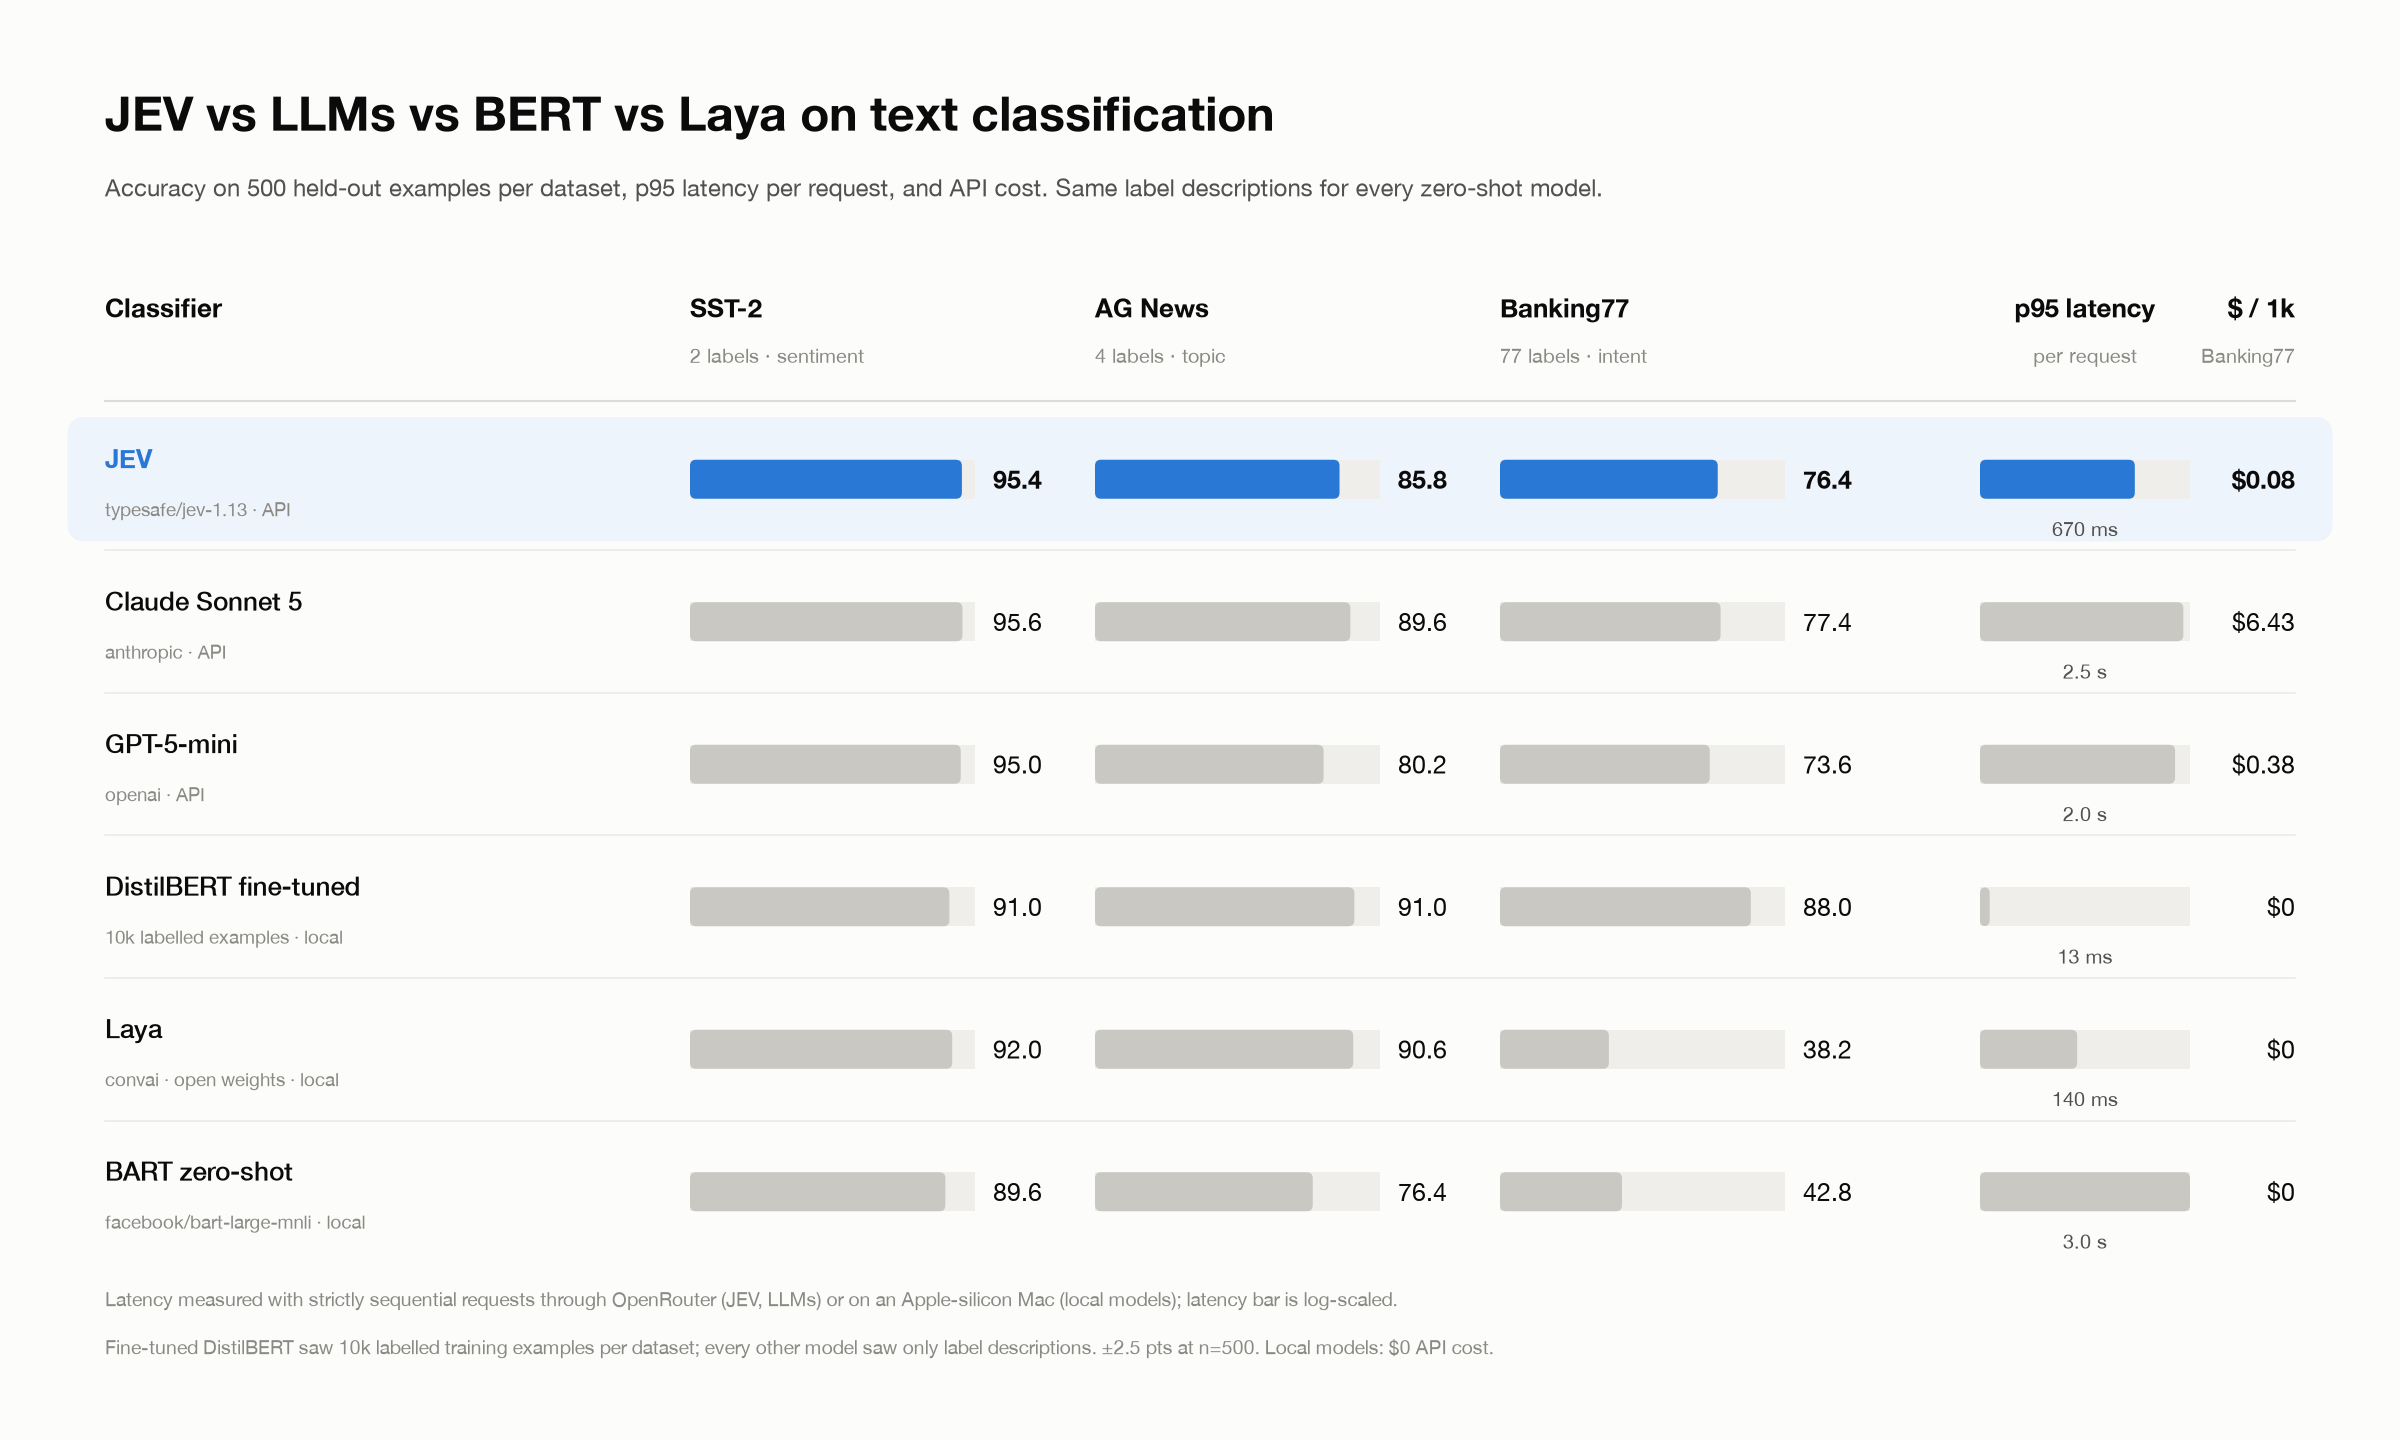
Benchmark TypeSafe JEV against LLMs, fine-tuned BERT, Laya and zero-shot NLI on text classification: accuracy, calibration, latency, throughput, cost
How it uses Jev
Is TypeSafe's JEV a better text classifier than LLMs, BERT, or the open-weights alternatives? This is a small, reproducible benchmark that runs six classifiers over three public datasets and reports accuracy, calibration, latency, throughput and cost side by side.
Getting started
Requires uv. Python 3.12 is pinned and fetched automatically.
- Language
- Python 100%
- License
- MIT
- Last activity
- Sep 2026
- Added
- 2026-09-22
- Stars at snapshot
- 5
- Status
- Community listing
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.