jev-reward-model-evaluation

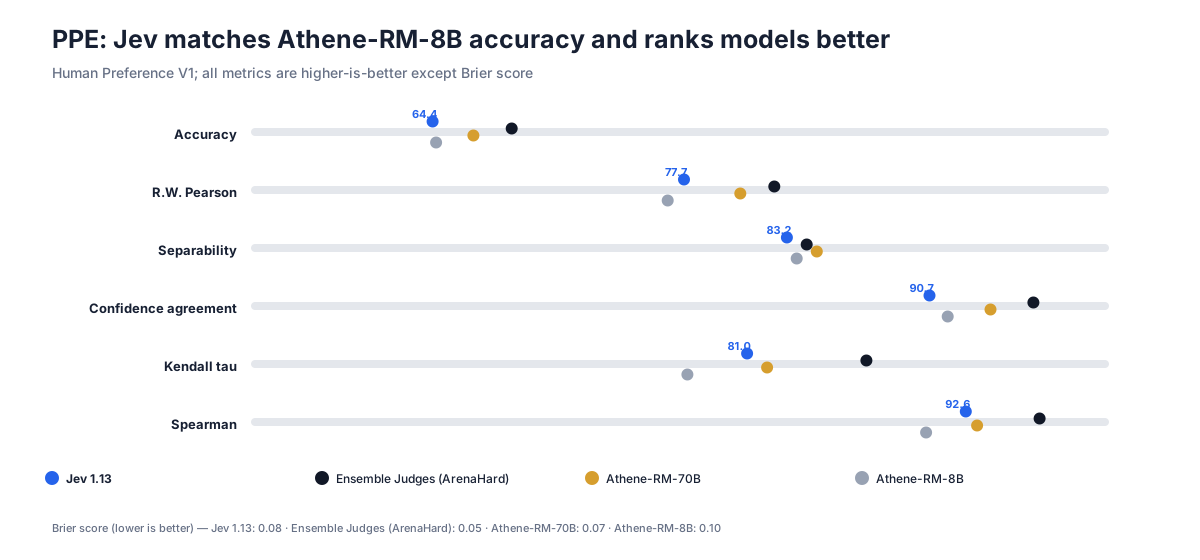
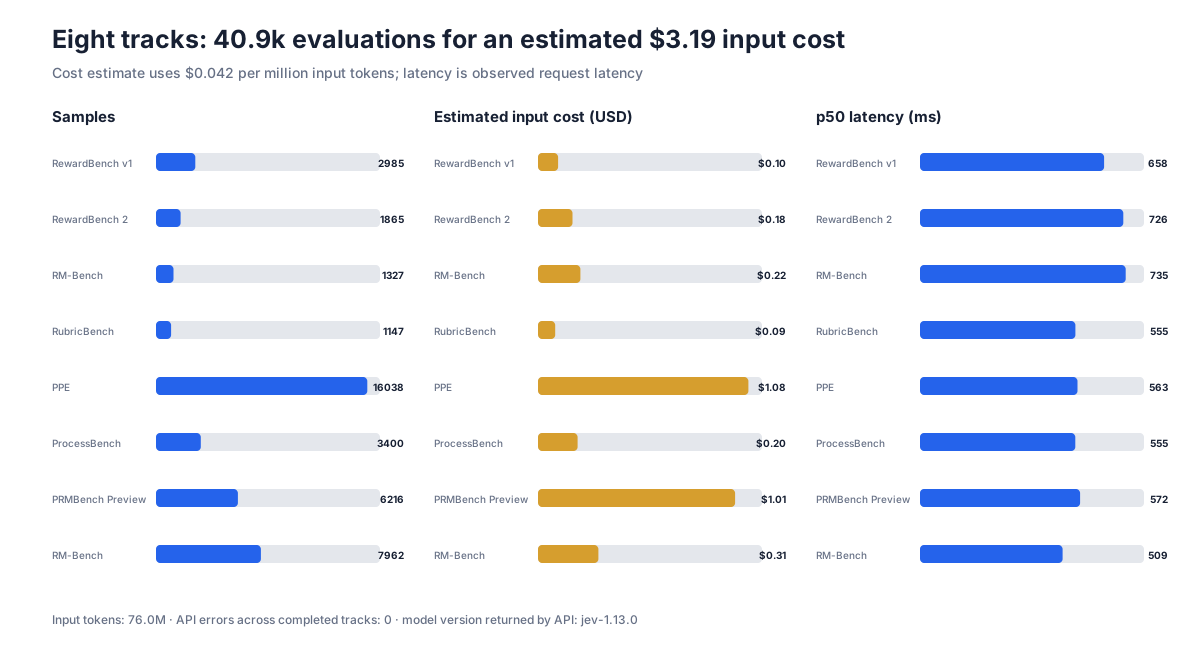
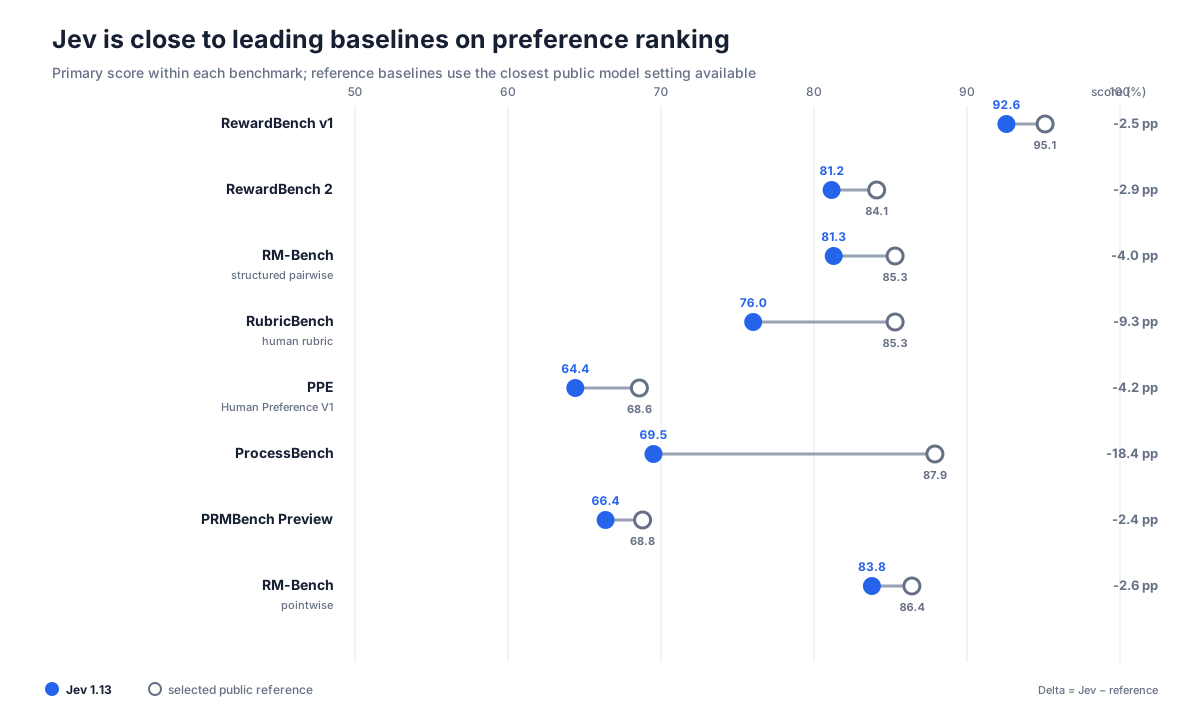
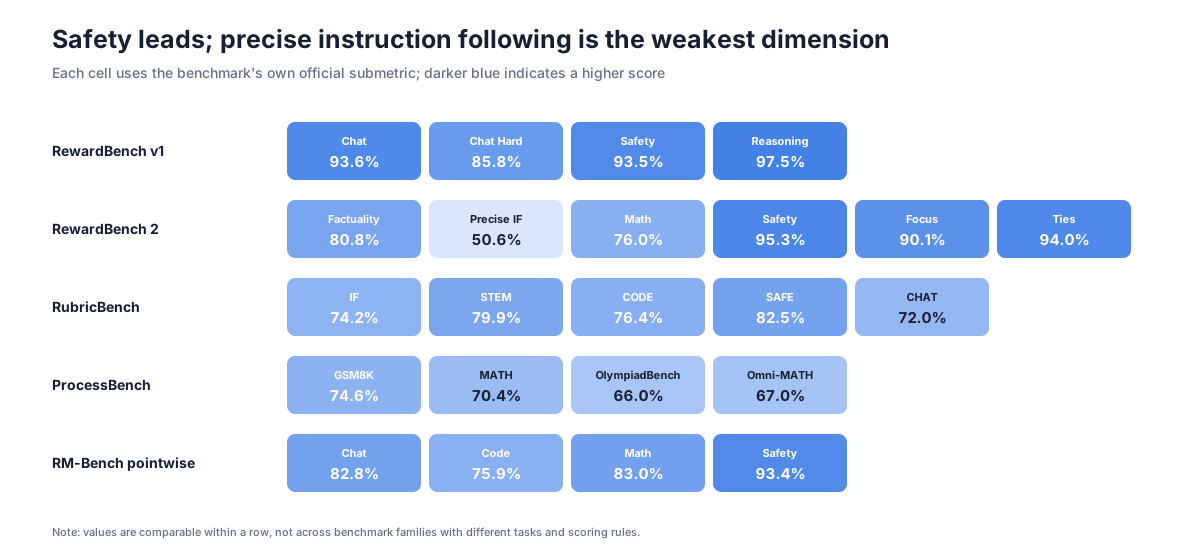
Jev 1.13 reward-model evaluation across 8 benchmark tracks, with an interactive report and 54-row SOTA comparison
How it uses Jev

A reproducible evaluation of Jev's structured classification API as a reward model, LLM judge, and process verifier.

Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README · the project website.

Keep exploring

Similar to jev-reward-model-evaluation

Browse all
typesafe-vs-deepseek project preview
Benchmarks & research
TypeSafe (Jev) vs DeepSeek-flash: side-by-side speed/token/cost/accuracy comparison across invoice extraction, email classification, and reranking
reflexbench project preview
Benchmarks & research
ReflexBench — open benchmark and evaluation harness for System One models and typed decision engines
jev-benchmarks project preview
Benchmarks & research
Probability-aware evaluation for typed decision models: calibration, selective risk, latency, and reproducible benchmarks.
Cerebellum-2B project preview
Browser & computer use
Non-Autoregressive AI Agent Decision Model. Open-source SOTA alternative to TypeSafe Jev. O(1) Tool Routing & DOM Automation on Qwen3.5-2B .
JevHarness project preview
Agent tooling
LLM-authored task-specific Jev harnesses with optional full-trajectory reward reflection and GEPA evolution.
jevelry project preview
Agent tooling
Use Jev everywhere to make & track decisions
jev-system-one project preview
Demos & playgrounds
A polished OpenAI + TypeSafe Jev terminal interface for answers with transparent decision reports
Demos & playgrounds
Talk nicely or nastily over time; structured state tracks the mood.
jev-board-lab project preview
Demos & playgrounds
Interactive explorer and Jev question workspace for Jev Board datasets.