jev-visual
An educational Jev-like visual inference experiment on Apple Silicon: shared context, direct candidate scoring, and local visual demos.
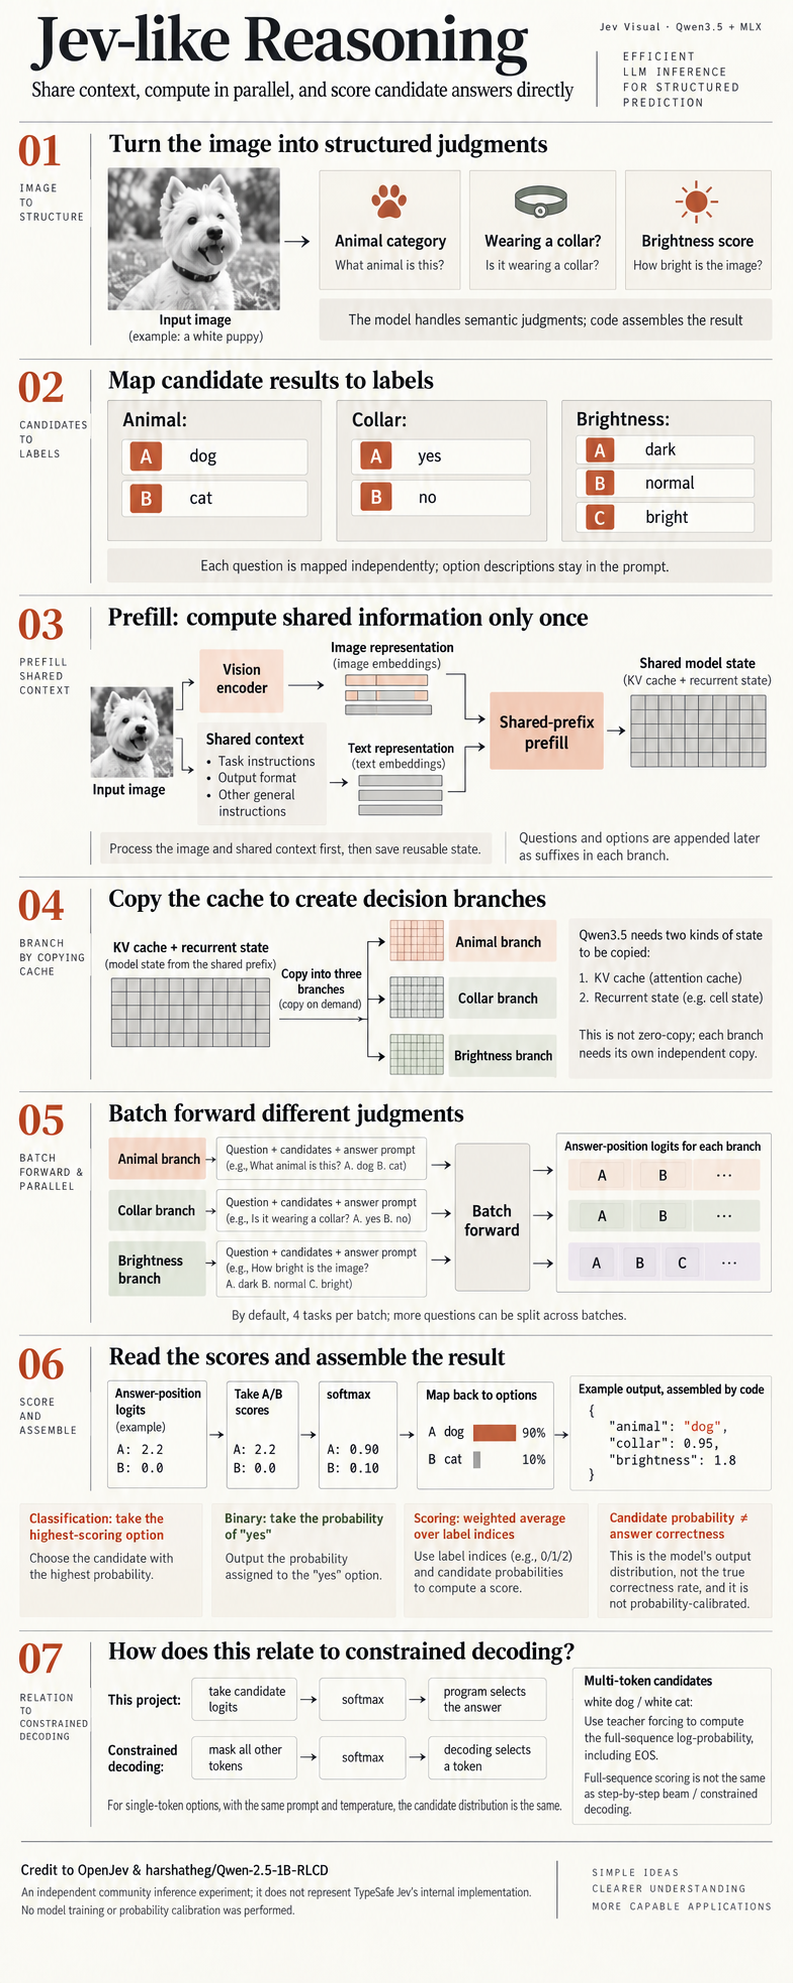
How it uses Jev
This project explores a Jev-like inference pattern for open multimodal language models. It avoids autoregressive structured generation by reusing shared multimodal context and directly scoring candidate outputs from model logits. This is an independent community implementation and does not claim to reproduce TypeSafe Jev's proprietary model architecture, RLCD training, calibration, or serving system.
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.