open-jev (JoshuaSP)

Typed JSON inference with DiffusionGemma, with Every and Jev benchmark results
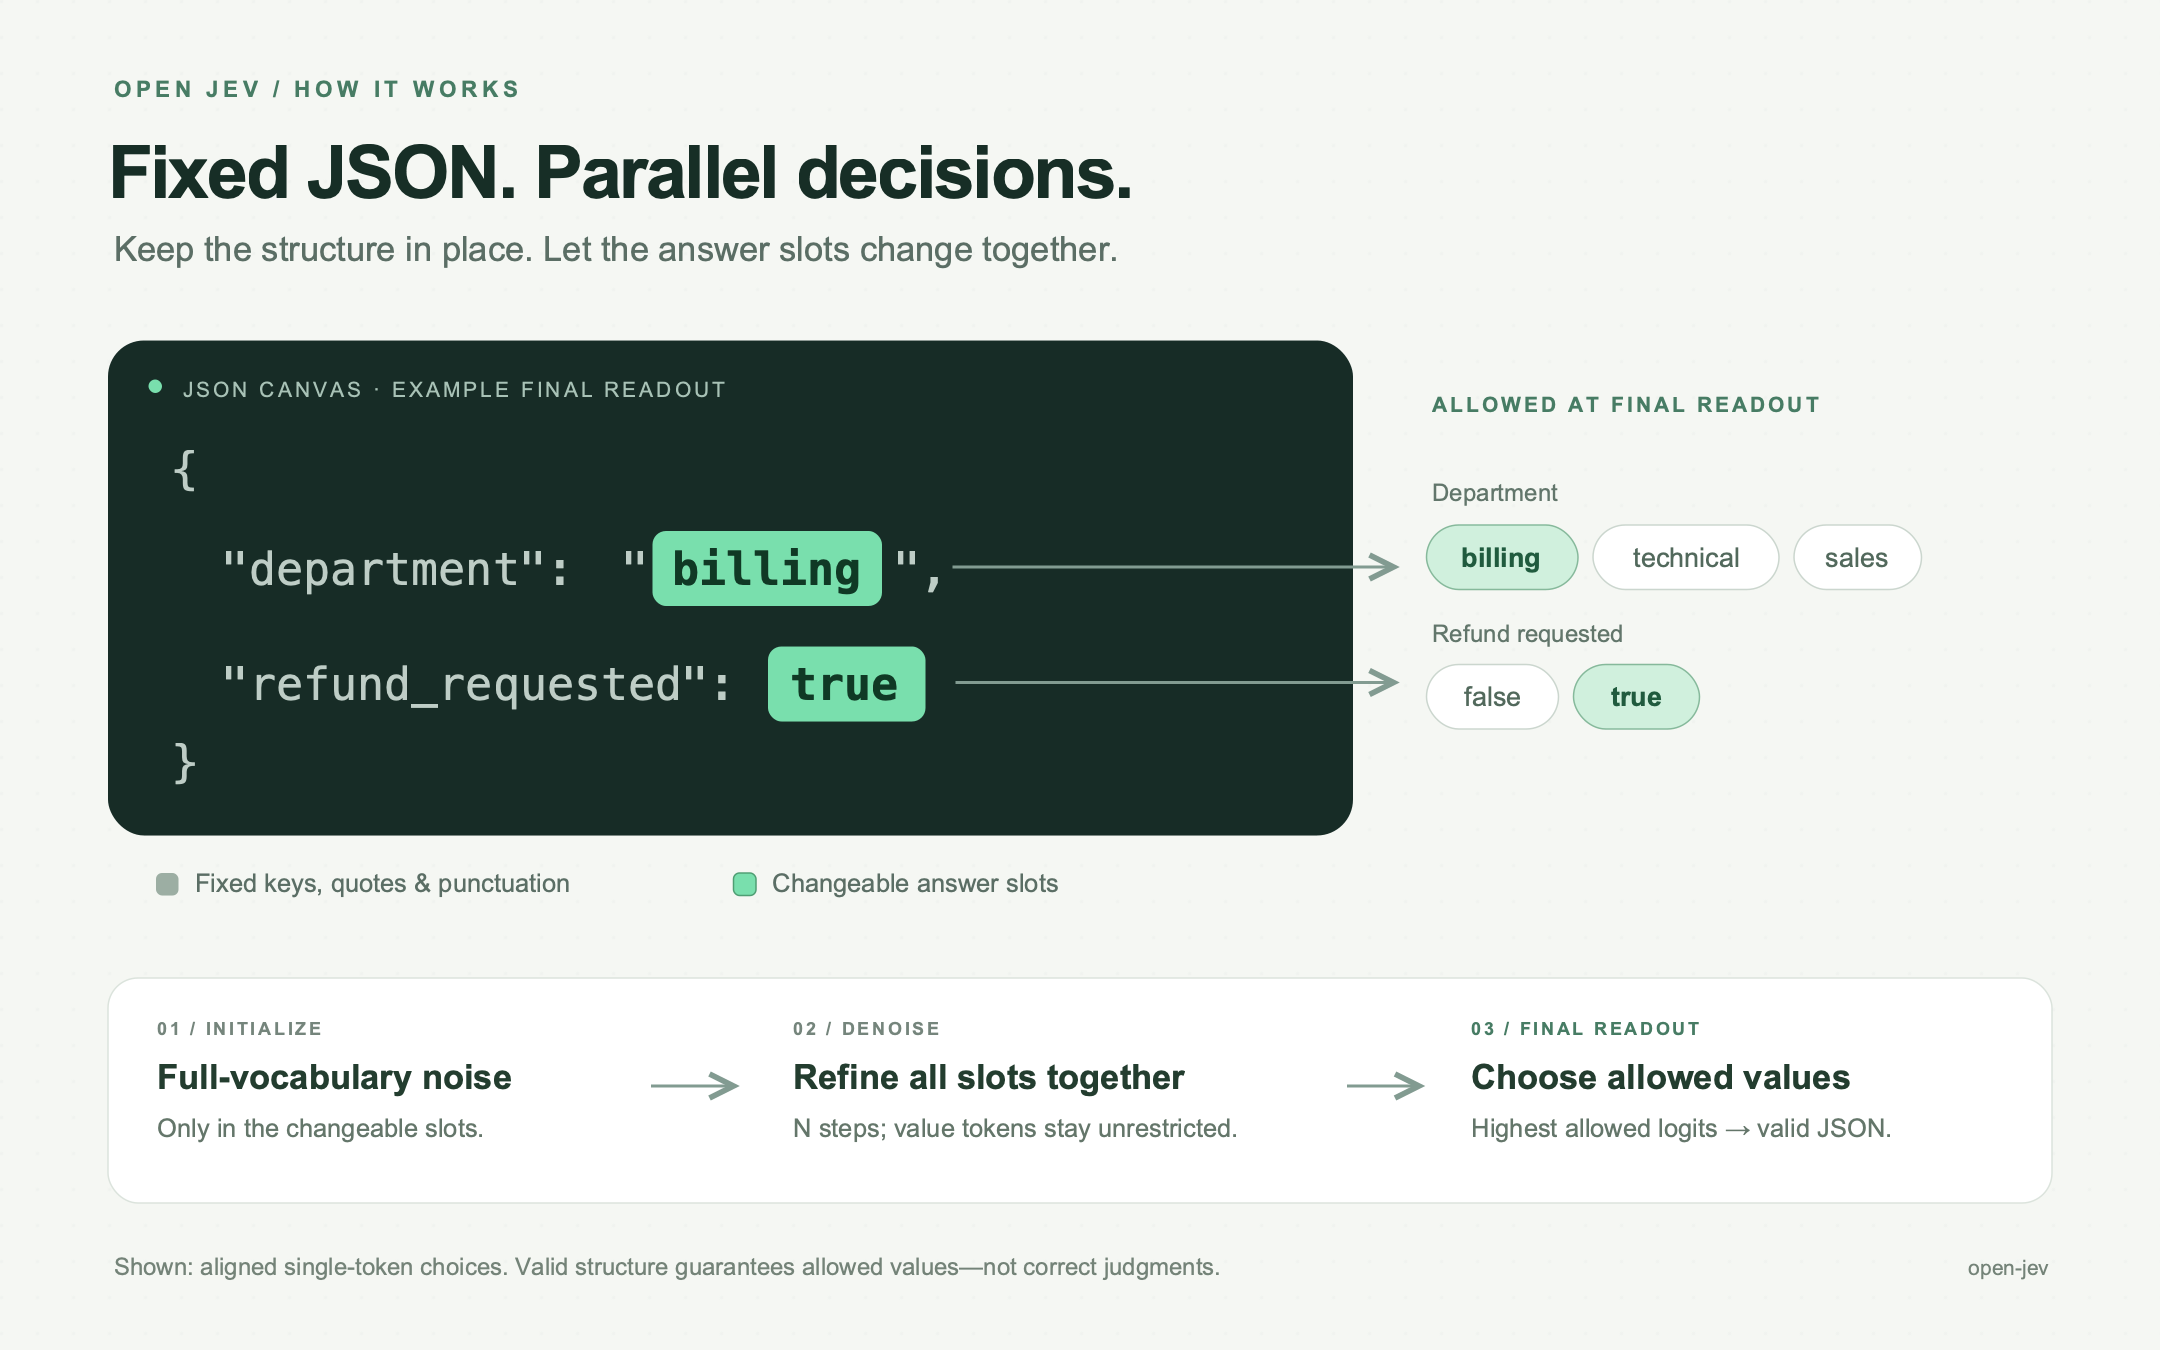
How it uses Jev

The goal is to explore how close an open diffusion model can get to TypeSafe AI's Jev on structured judgments. This is an independent experiment, not a reproduction of Jev's architecture, training, calibrated probabilities, or published workflow scores.

Getting started

Requires Python 3.11+, a Modal account, and a Hugging Face token with access to the model. Accept the model's access terms on Hugging Face first.

Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.

Keep exploring

Similar to open-jev (JoshuaSP)

Browse all
openjev project preview
Benchmarks & research
Open, Jev-compatible System One decision server on DiffusionGemma
open-alternative-jev project preview
Jev alternatives & open source
Open alternative to Jev: typed, calibrated decisions from any open-weights LLM in one forward pass (HF + vLLM), with benchmarks
Verdict-open-jev project preview
Jev alternatives & open source
Non-autoregressive decision engine on ModernBERT (151M) with calibrated uncertainty (RLCD), TypeSafe AI Jev benchmark audit, and in-browser WebGPU playground
openvons project preview
Jev alternatives & open source
openvons (open-Jev): 有限選択肢に確率で答える判断層 — テキスト / 画像 / 日本語音声コマンド
system-one project preview
Benchmarks & research
Batched single-token choice inference for open language models, compatible with TypeSafe
reflexbench project preview
Benchmarks & research
ReflexBench — open benchmark and evaluation harness for System One models and typed decision engines
jev-cli project preview
Applications
CLI for TypeSafe AI's Jev evaluation model — typed questions in, structured JSON answers out
jev-reranker (shinpr) project preview
Rerank, filter, and compress JSON search results with TypeSafe AI's Jev.
winnow project preview
Agent tooling
A calibrated context sieve for Claude Code: every tool result is judged by a System One model before it enters context.