jev-korean-benchmark

Reproducible early-access evaluation of Jev on Korean understanding and medical text, with runtime and cost evidence
How it uses Jev

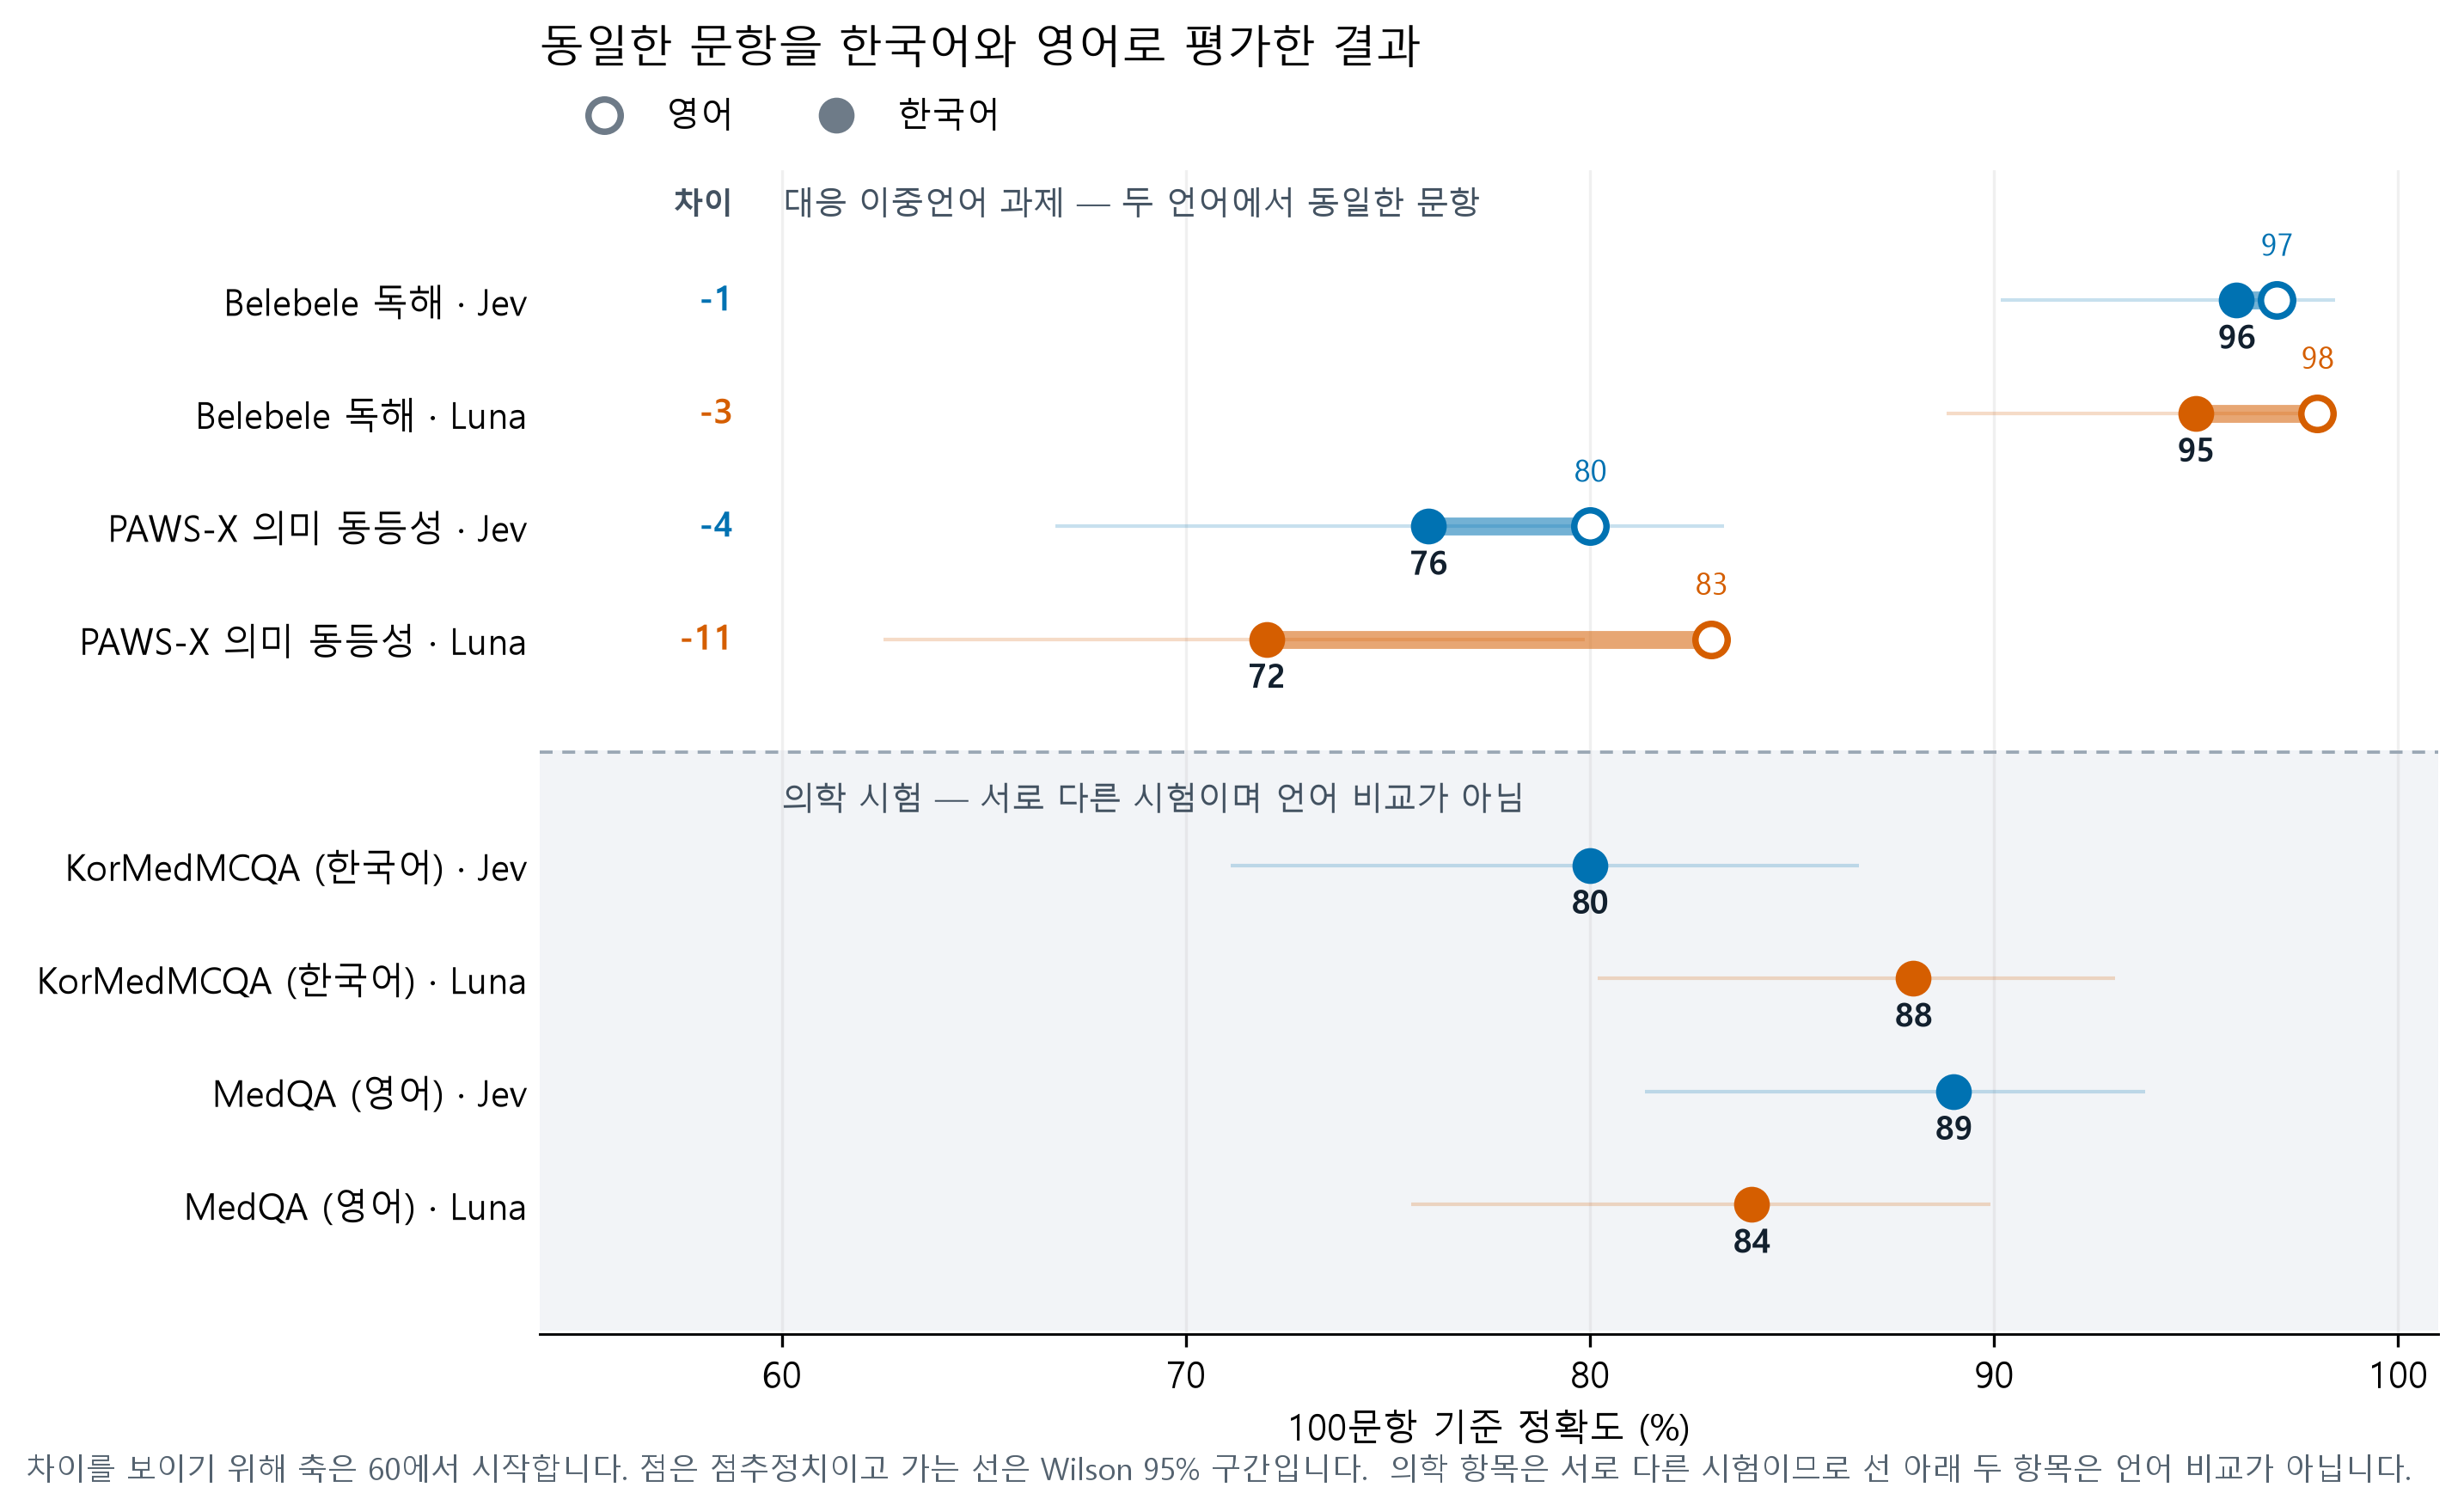
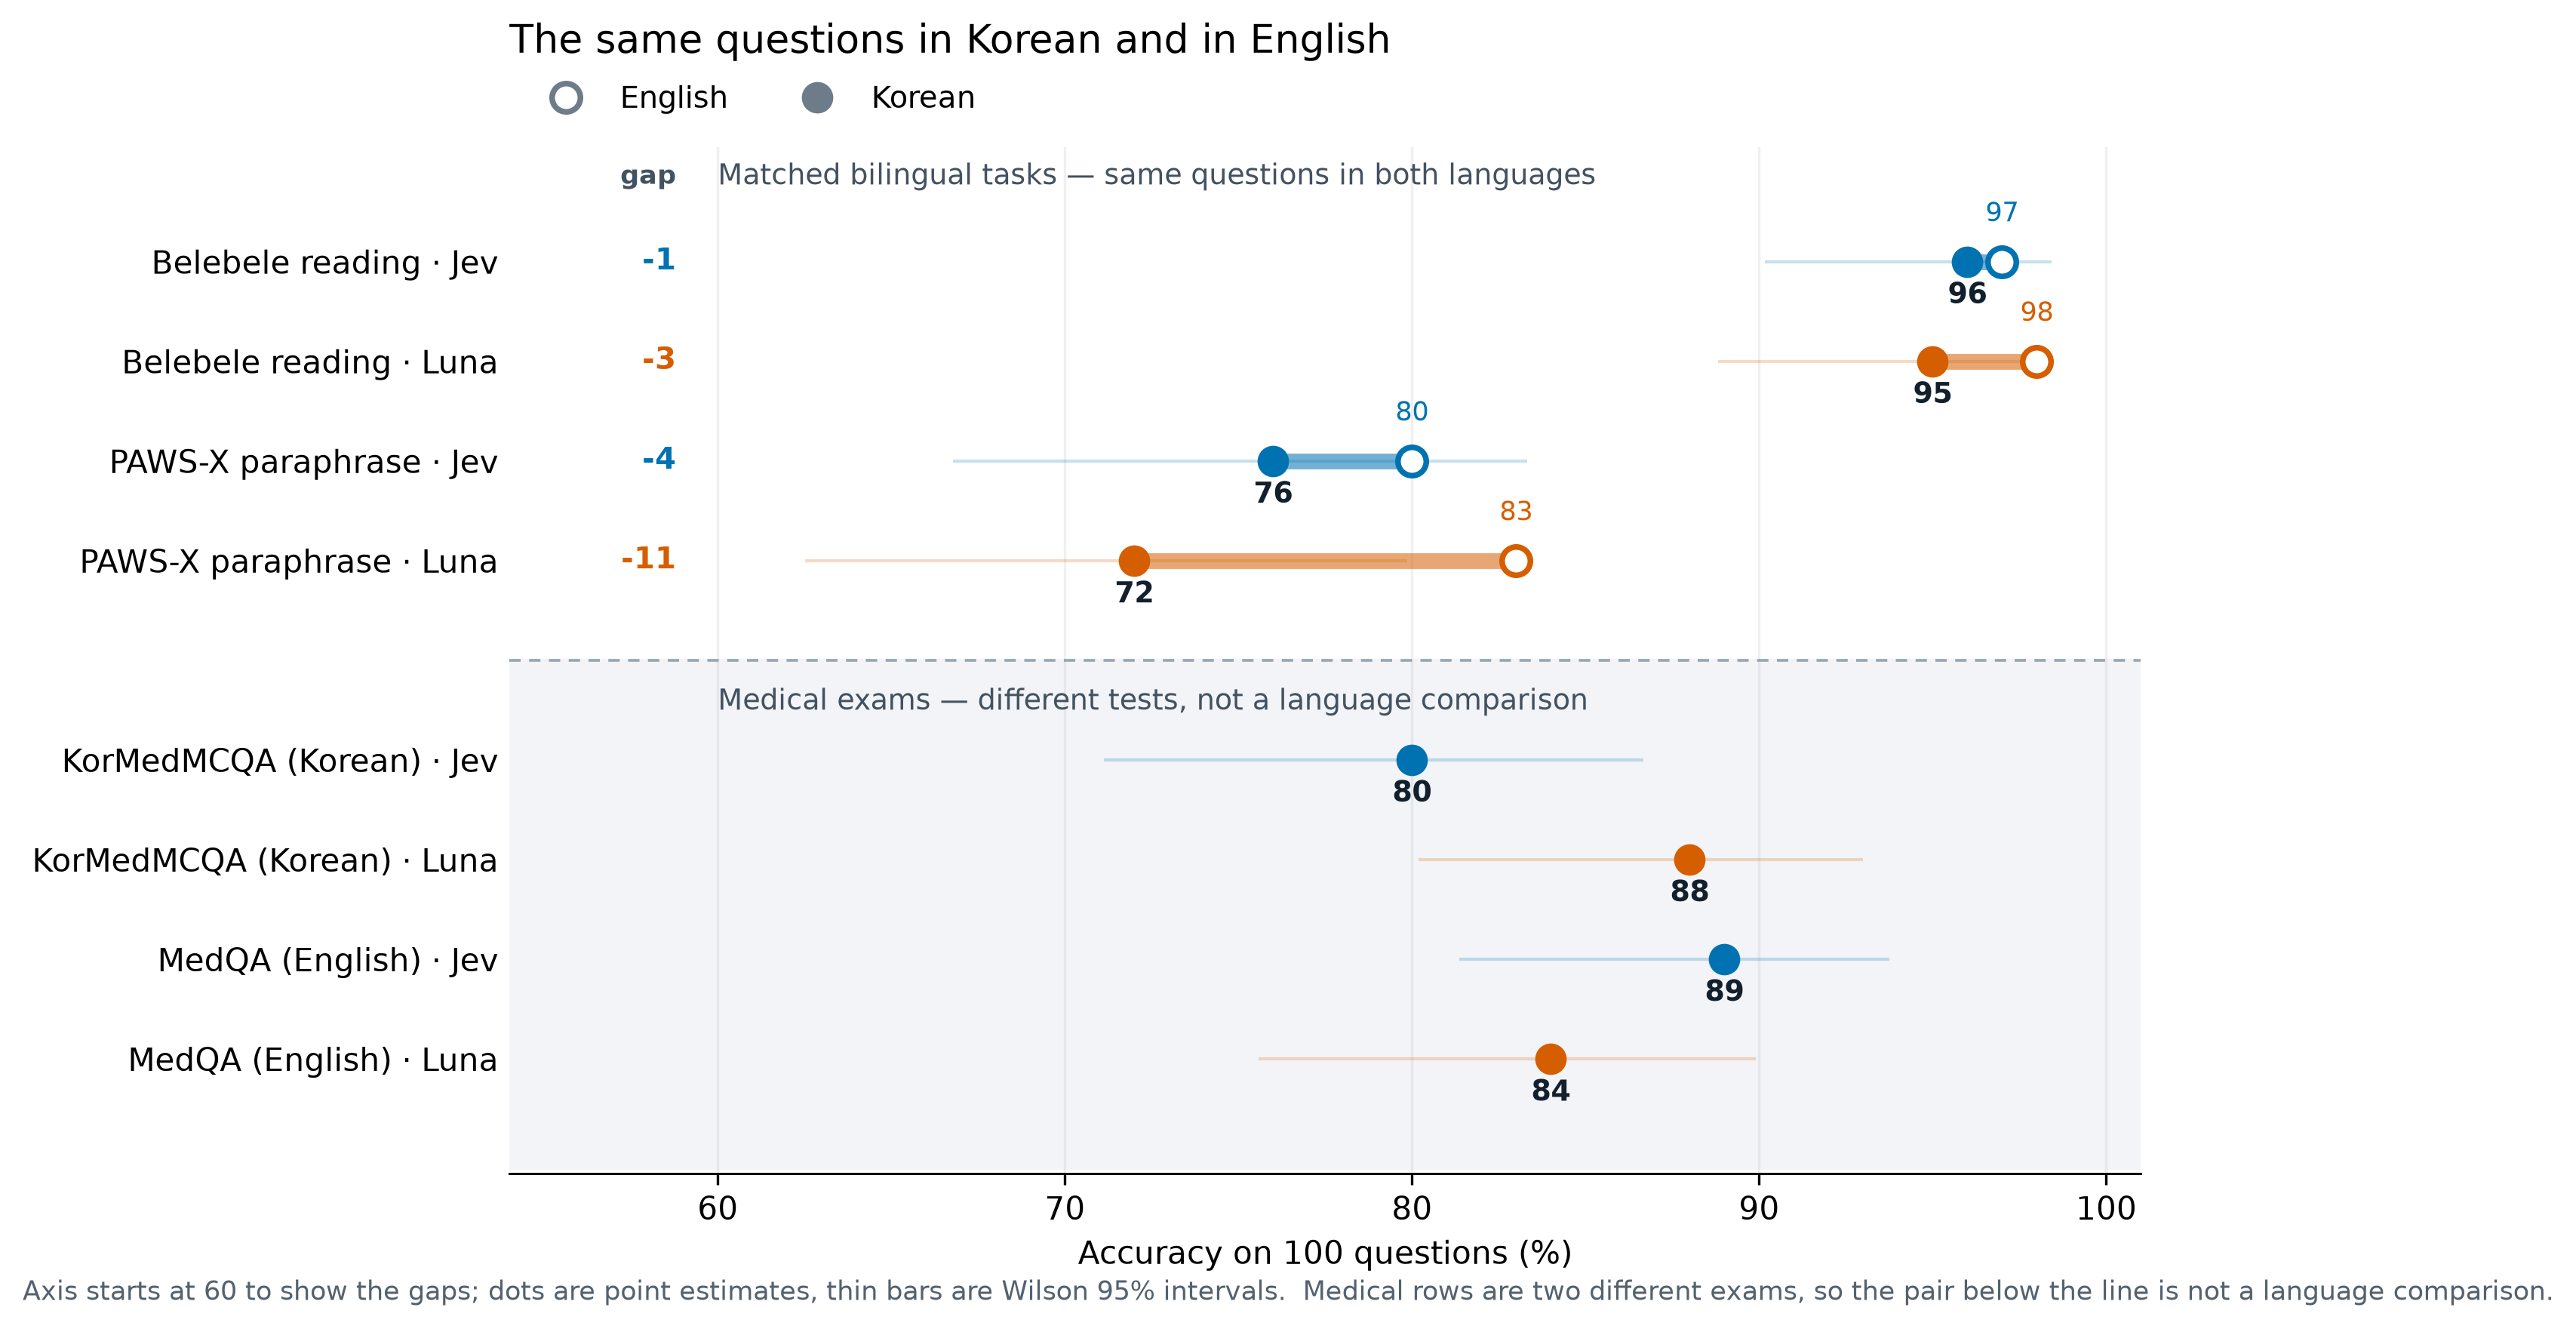
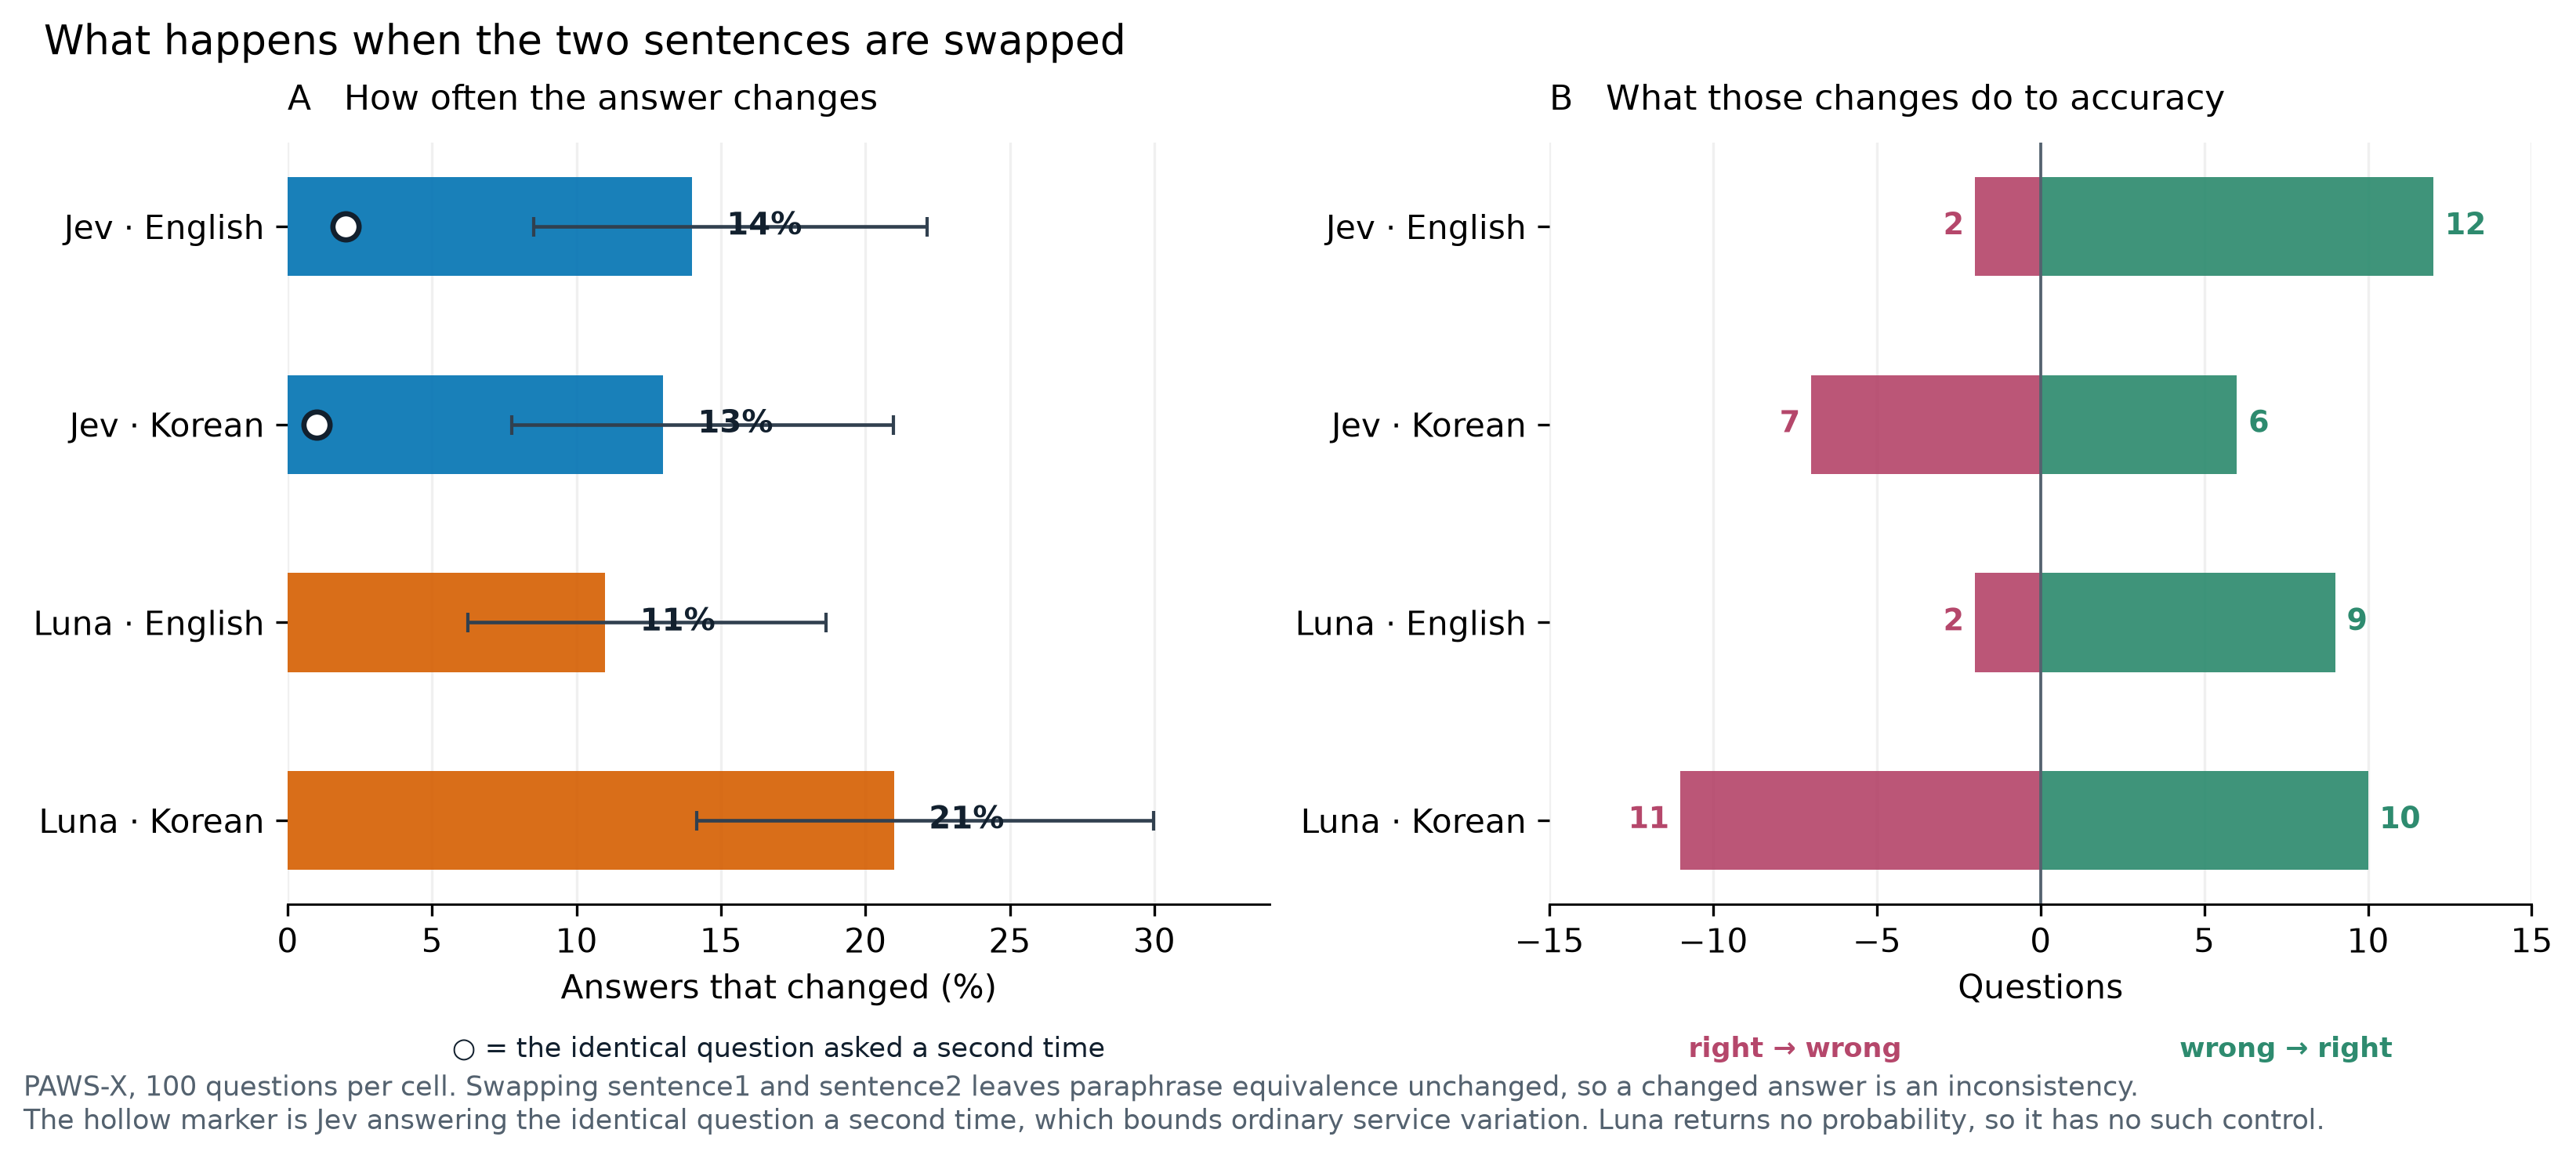
Jev in Korean: a 100-question sample check

Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README · the project website.
Keep exploring

Similar to jev-korean-benchmark

Browse all
jev-benchmarks project preview
Benchmarks & research
Probability-aware evaluation for typed decision models: calibration, selective risk, latency, and reproducible benchmarks.
jev-rag-benchmark project preview
Benchmarks & research
Reproducible benchmark for measuring Jev reranking quality, latency, and cost in RAG
jev-phishing-bench project preview
Benchmarks & research
Jev (TypeSafe) vs Claude Haiku 4.5 on 2 000 phishing emails: accuracy, calibration, latency, cost. Reproducible benchmark.
limpet project preview
Agent tooling
A Stop hook that stops your coding agent from stopping too early. Plain-language rules, judged by jev.
jev-search project preview
Agent tooling
Search the web with TypeSafe's Jev: source selection, query understanding and relevance ranking. Built with Search1API.
hermes-jev-router project preview
Agent tooling
Experimental Hermes plugin: Jev-assisted model routing plans with budget and capability constraints. API access pending.
aside-jev project preview
Browser & computer use
Aside agents decide with TypeSafe Jev (System One: Choice/Score/Noul). Not a Cua binding — Jev is the model, Aside is the browser runtime.
Browser & computer use
A browser agent that turns a single goal into a sequence of lightning-fast actions.
werr project preview
Demos & playgrounds
Zero-memory System-1 decision engine & TypeSafe Jev wire-compatible runtime powered by Mandelbrot wave dynamics (JevBench #1).