jeval
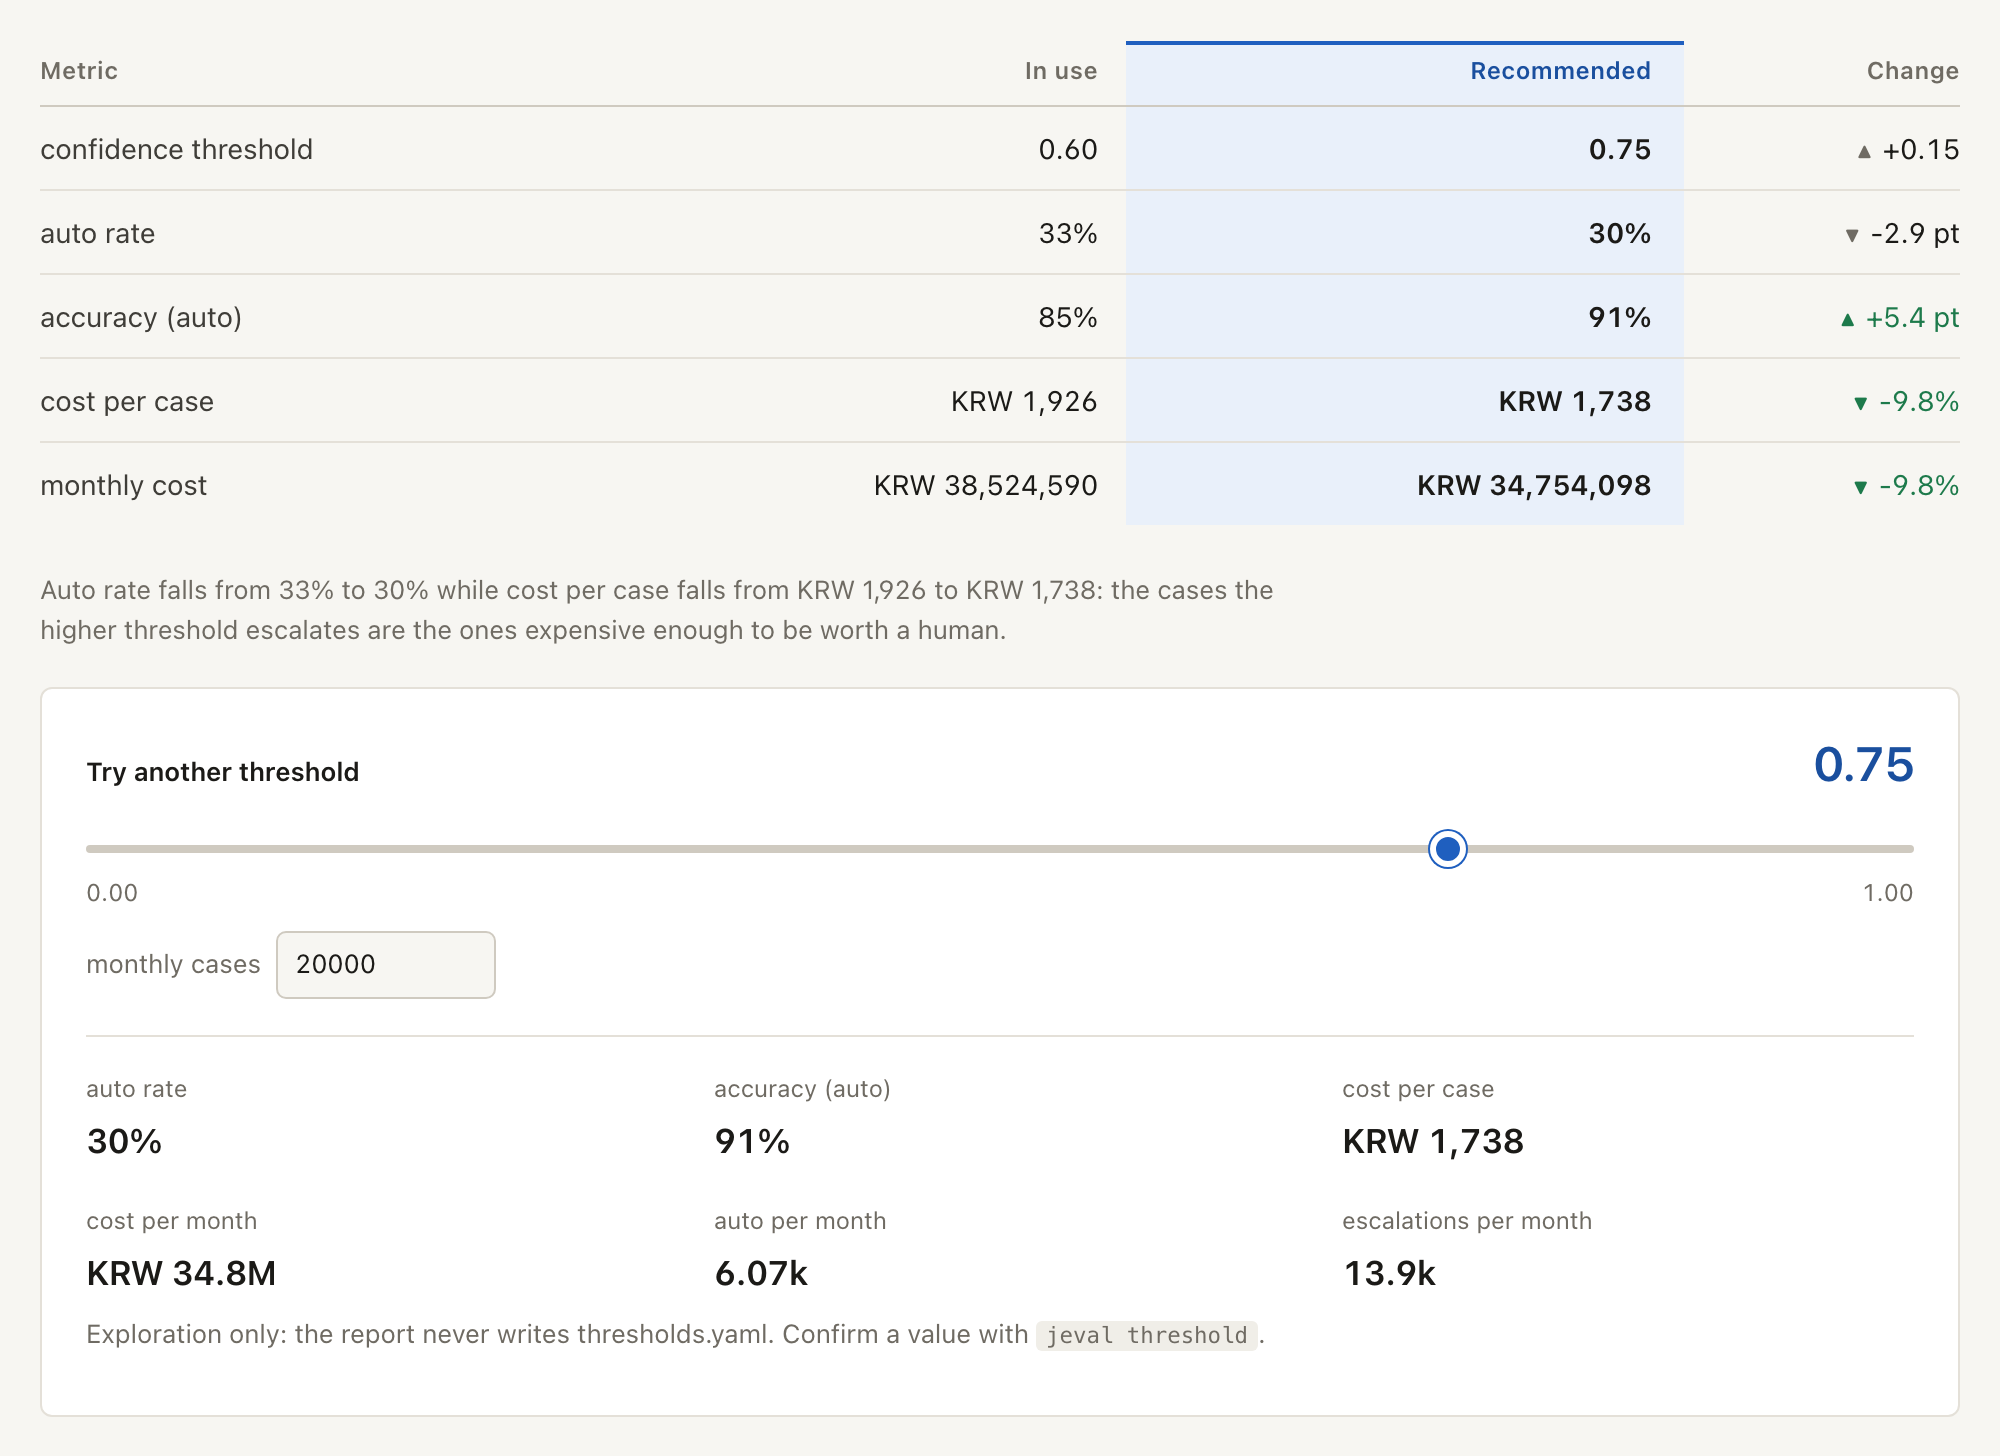
Measures what your Jev classifier's confidence is really worth, and sets the human hand-off line from what a mistake costs.
How it uses Jev
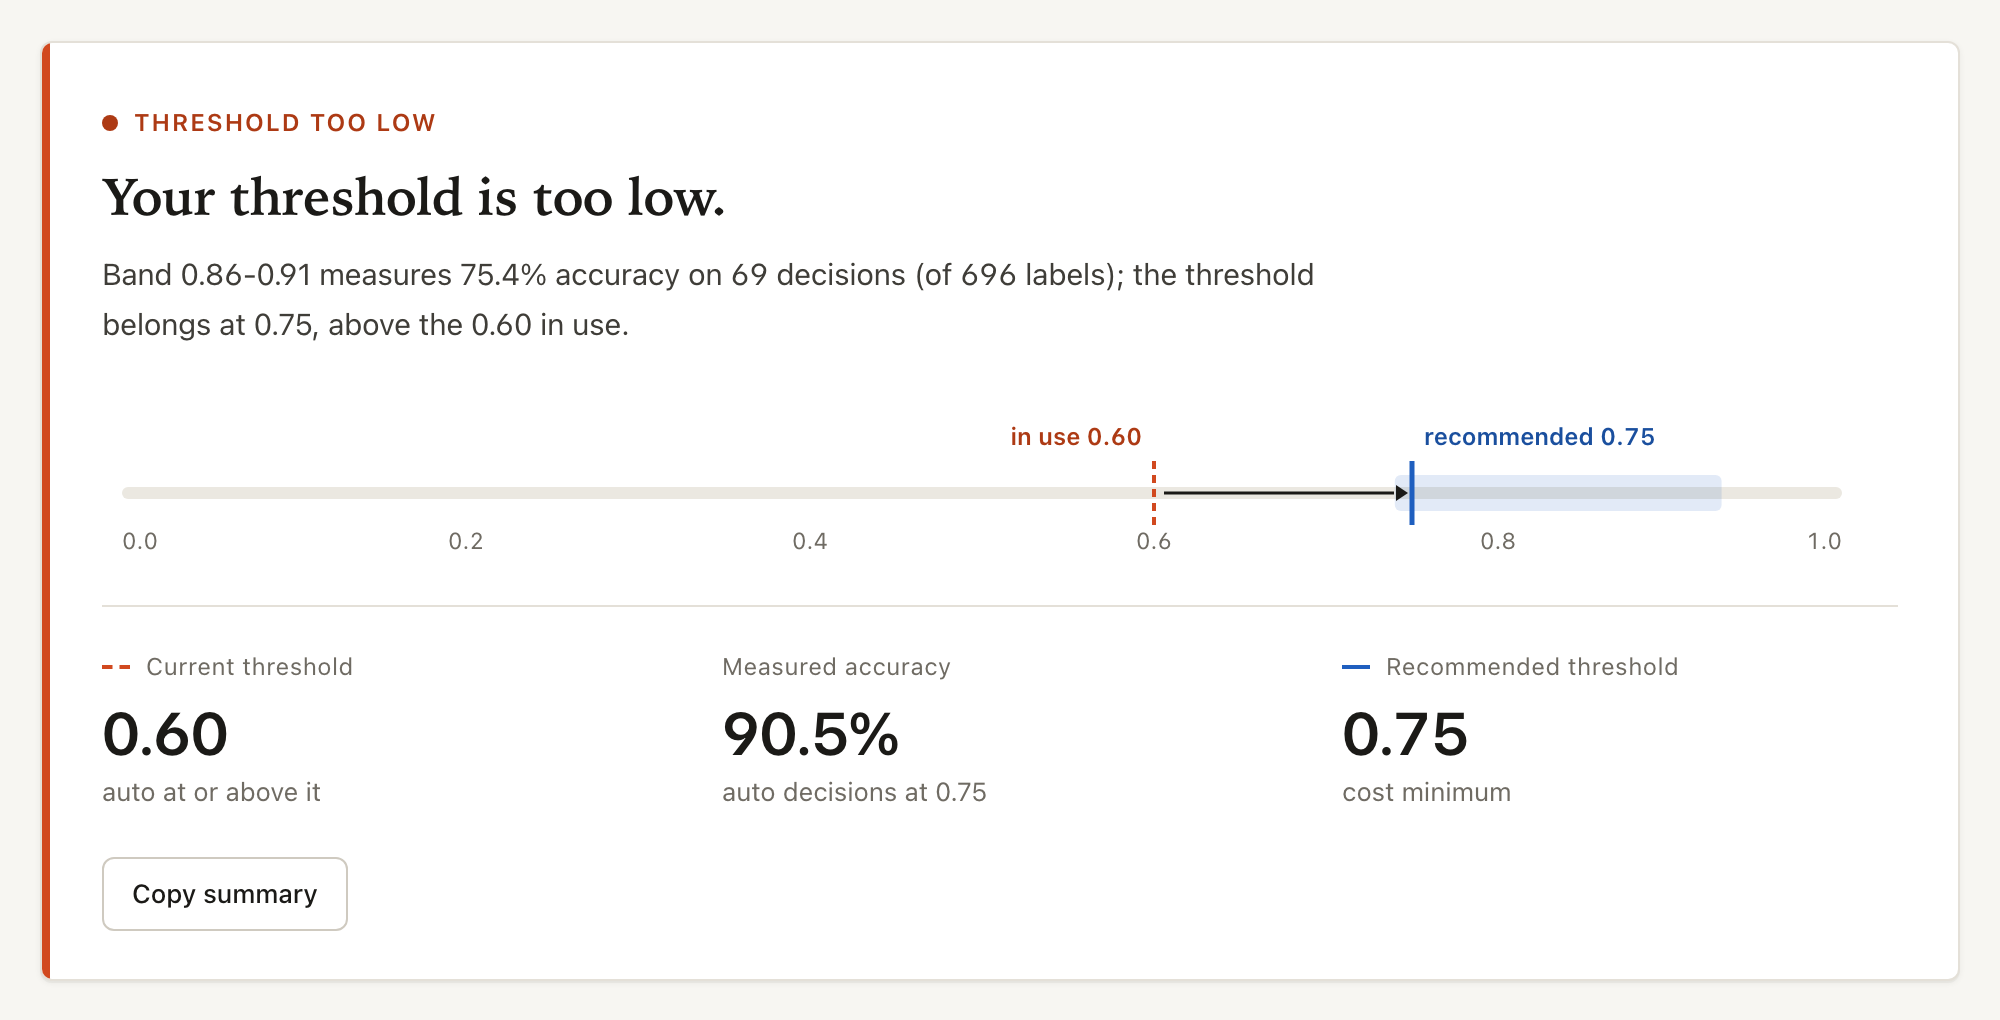
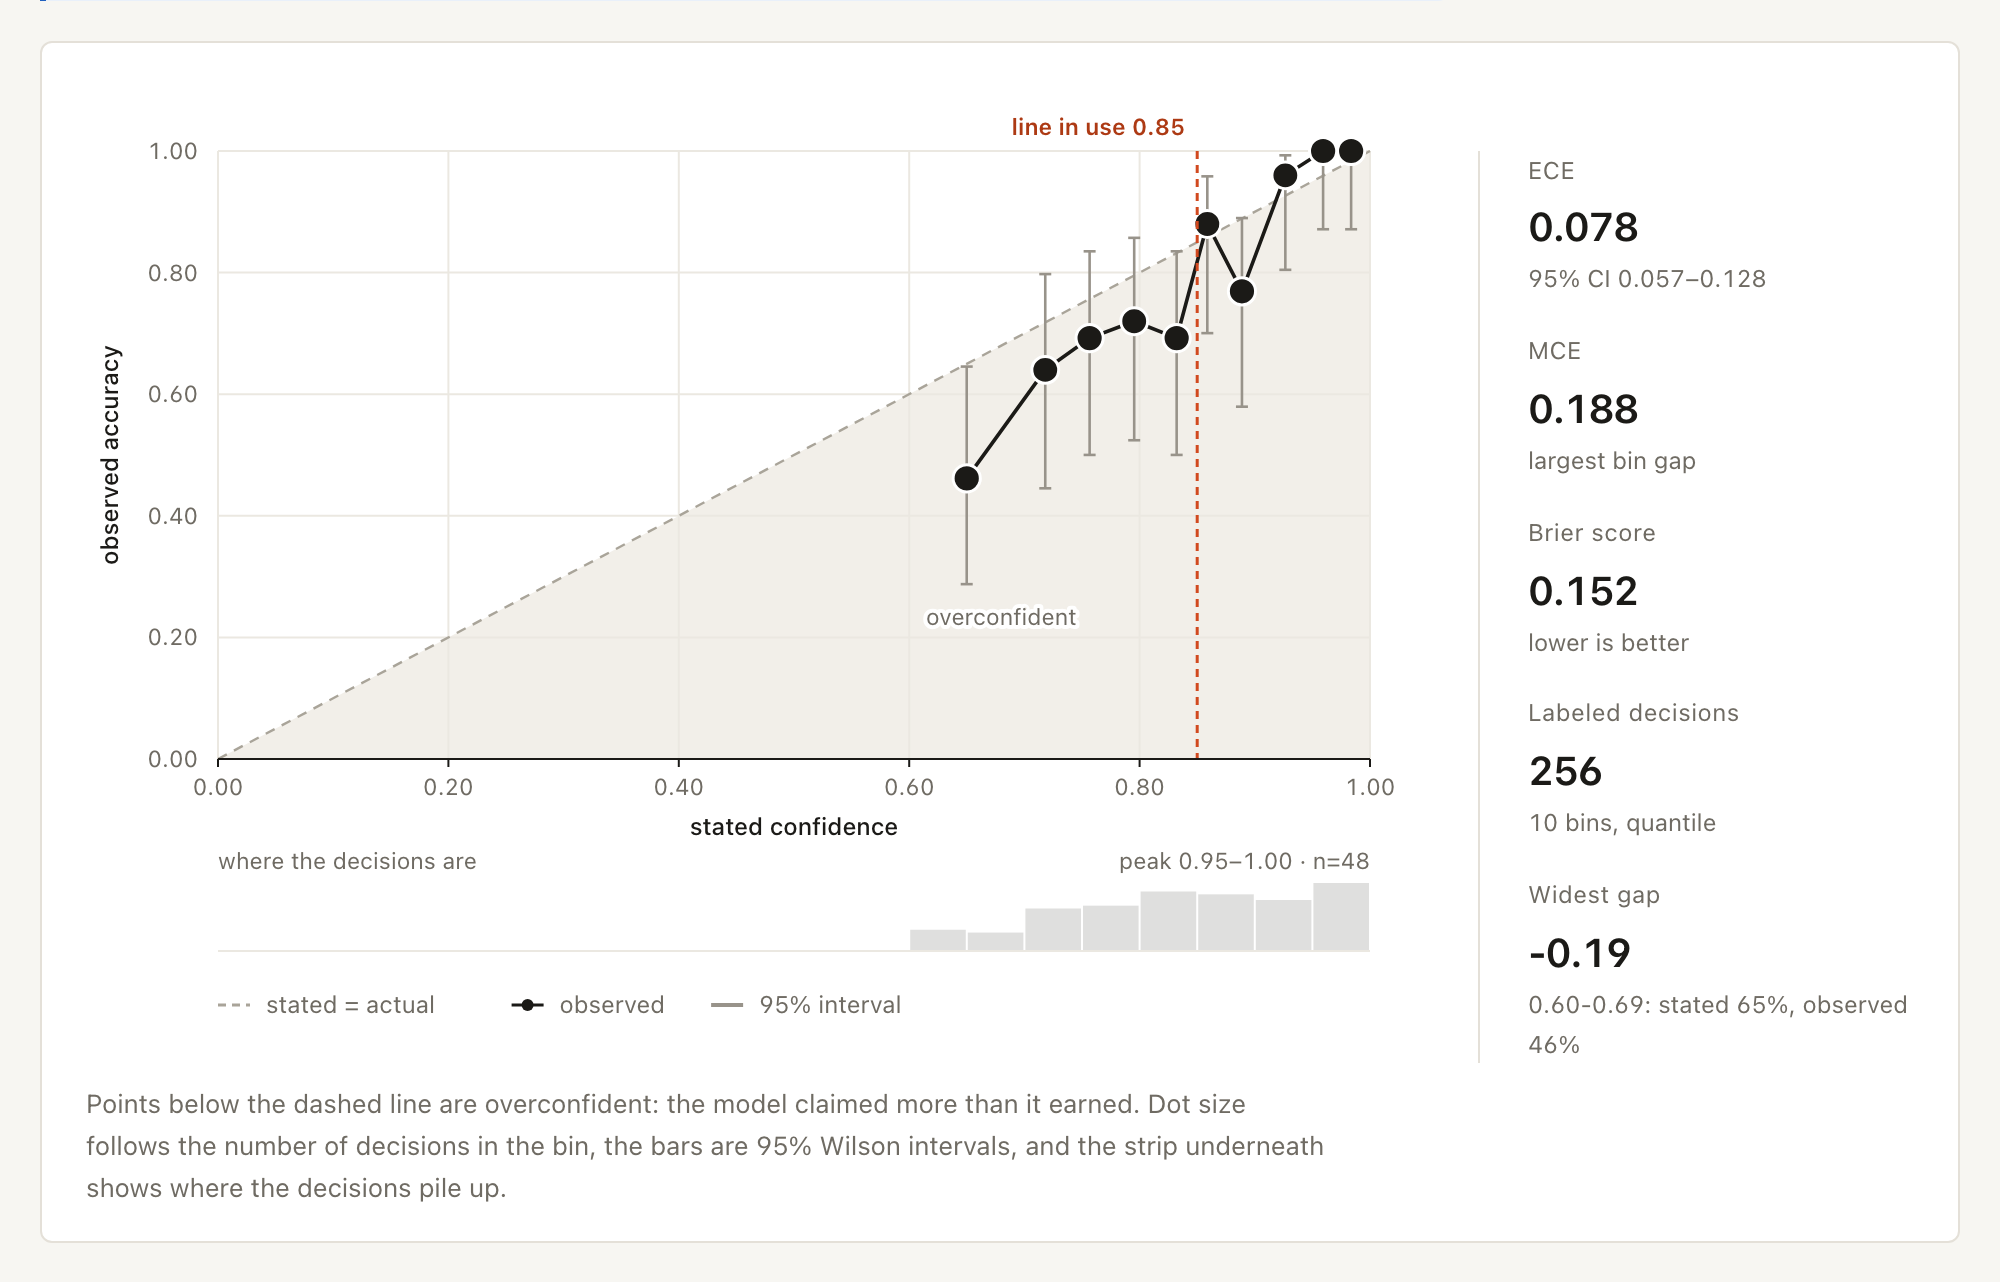
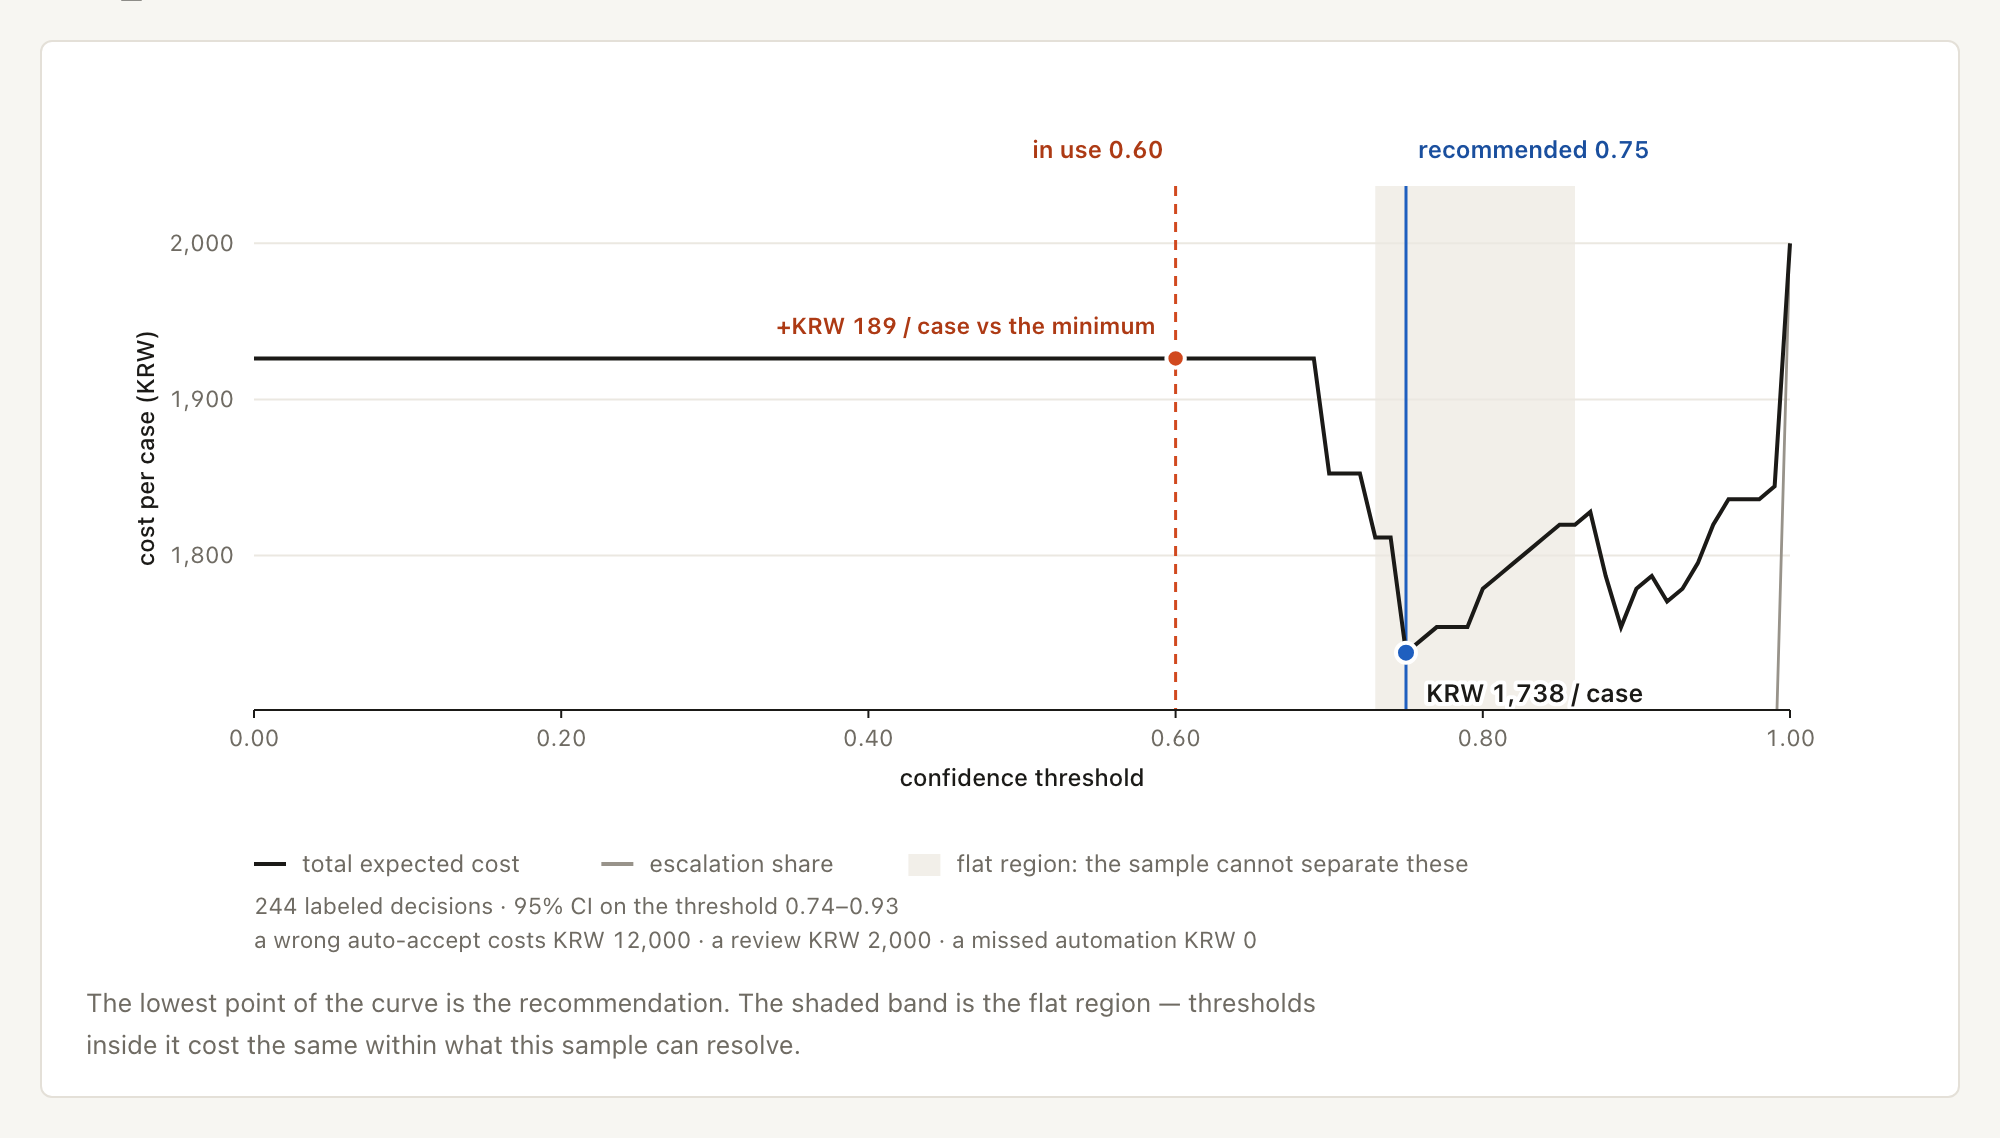
Command What it does Status --- --- --- jeval init create .jeval/ config and the ingest map implemented jeval ingest JSONL/CSV logs to decision records; --preset jev-native reads a decision API's own response log; --labels brings in human answers implemented jeval report the report itself: verdict, reliability, cost, impact, segments, score questions, labels and correction, drift, data quality — one HTML file, or --…
Getting started
Nobody wants to learn nine commands. Hand an agent one sentence and take the report back:
- Languages
- Python 98% · Shell 2%
- License
- Apache-2.0
- Latest release
- v0.1.8
- Last activity
- Sep 2026
- Added
- 2026-09-23
- Stars at snapshot
- 16
- Status
- Community listing
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.