jevcal

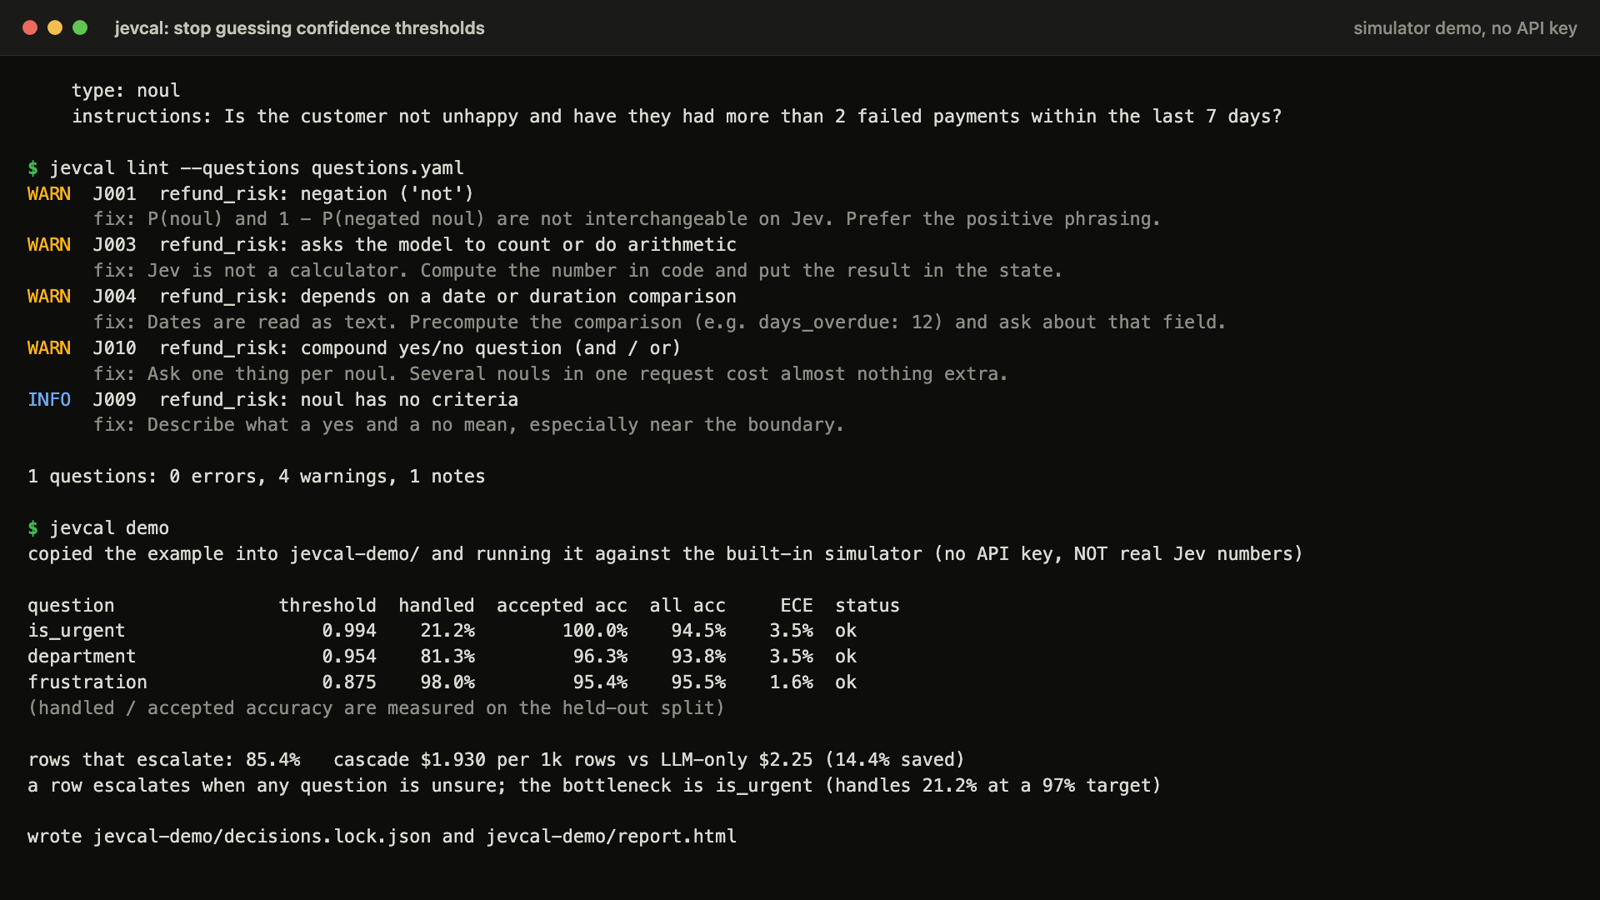
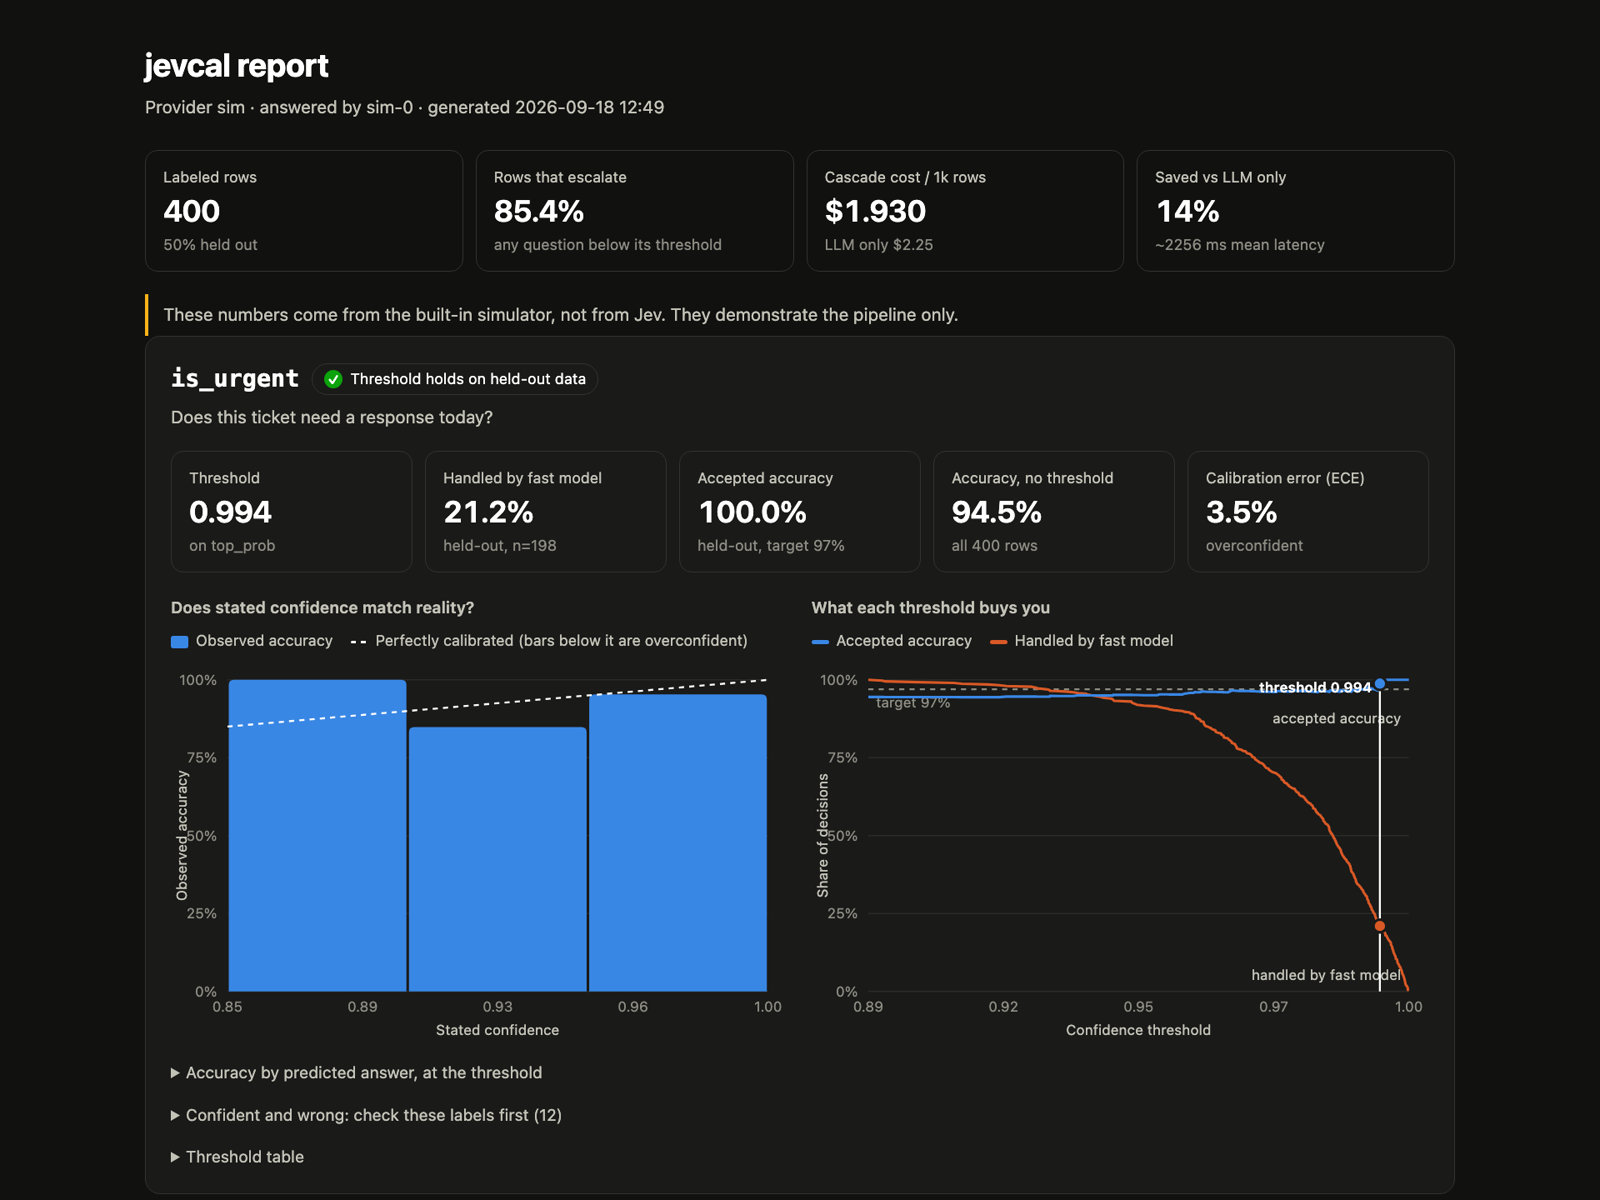
Stop guessing confidence thresholds: calibrate, threshold, and drift-check typed decision models (TypeSafe Jev) against an LLM teacher.
How it uses Jev

Built for Jev (TypeSafe's System One model), and for anything else that returns answers with probabilities.

Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.

Keep exploring

Similar to jevcal

Browse all
jev-agent-failure-benchmark project preview
Benchmarks & research
Benchmarking Jev (Typesafe.ai) against a strong LLM on the Who&When Pro agent-failure-attribution benchmark (text subset).
poorjev project preview
Benchmarks & research
Open-source, local Jev alternative: a System One decision layer with provably calibrated confidence (ECE 0.170→0.071). Typed decisions, runs offline, no API key, no waitlist.
jev-spec project preview
Agent tooling
⚡ Catch spec drift on every commit: check your code against your Markdown specs with TypeSafe AI's Jev model.
clear-head project preview
Agent tooling
Claude Code Stop hook that checks an AI assistant's claims against what it actually read this session, using TypeSafe's Jev as the judge
jev-agent-skill-router project preview
Typed, confidence-aware agent skill routing with TypeSafe Jev.
System One adapter (Python) project preview
Official drop-in TypeSafeClient replacement backed by OpenAI, Anthropic, and compatible LLM APIs, for comparing Jev against chat models.
zod-jev project preview
SDKs & clients
Zod validates the shape, Jev validates the meaning: semantic checks on request bodies become calibrated probabilities you threshold in code.
jev_local project preview
Jev alternatives & open source
Replicating Jev with a local LLM