jev-agent-failure-benchmark
Benchmarking Jev (Typesafe.ai) against a strong LLM on the Who&When Pro agent-failure-attribution benchmark (text subset).
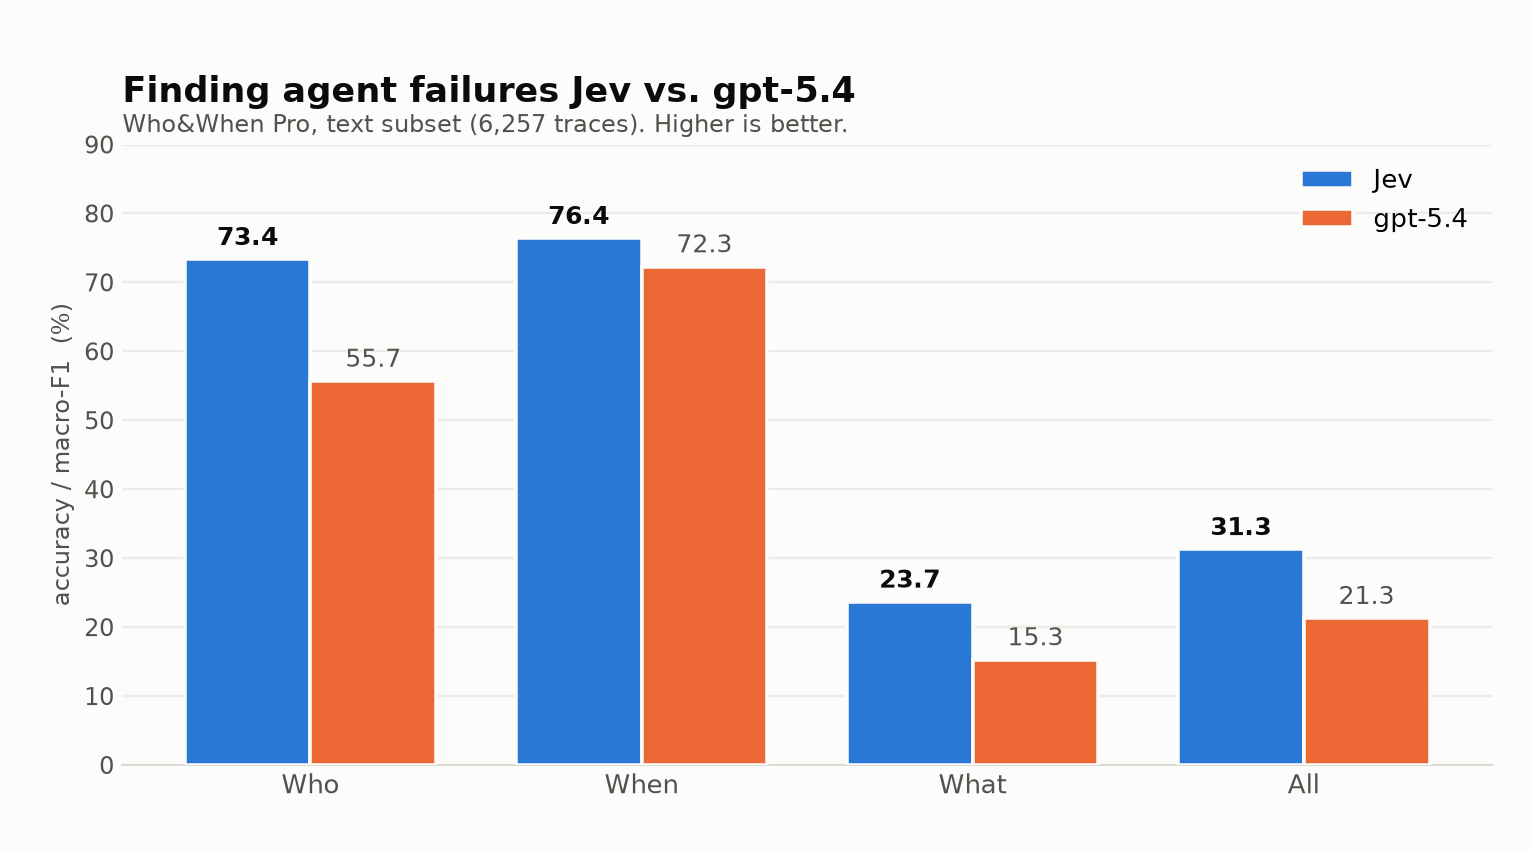
How it uses Jev
Can a fast, cheap decision model find what broke an AI agent as well as a frontier LLM? This benchmarks Jev (Typesafe.ai) on the text subset of Who&When Pro , an agent-failure-attribution benchmark: given a failed multi-agent run, predict the responsible agent , the decisive step , and the error type .
Getting started
Get the pinned text subset ( 72 MB, not redistributed here):
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.