jev-benchmark
Benchmarks and a playground for TypeSafe's Jev (System One) model: chess, and who-is-the-player-talking-to for speech-to-text game NPCs
How it uses Jev
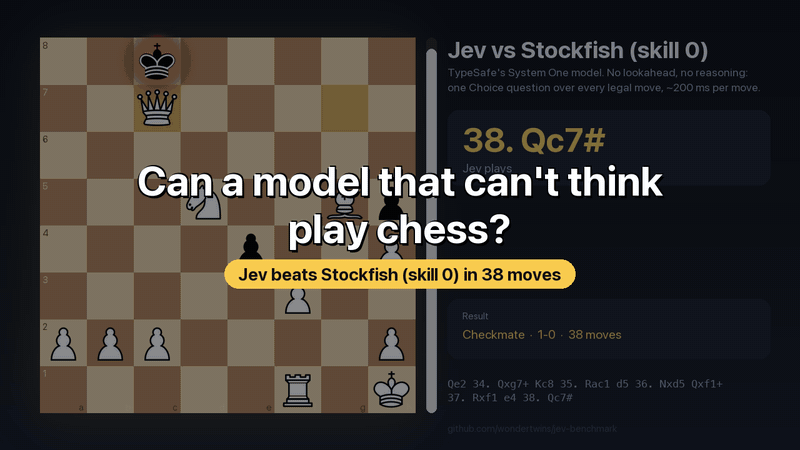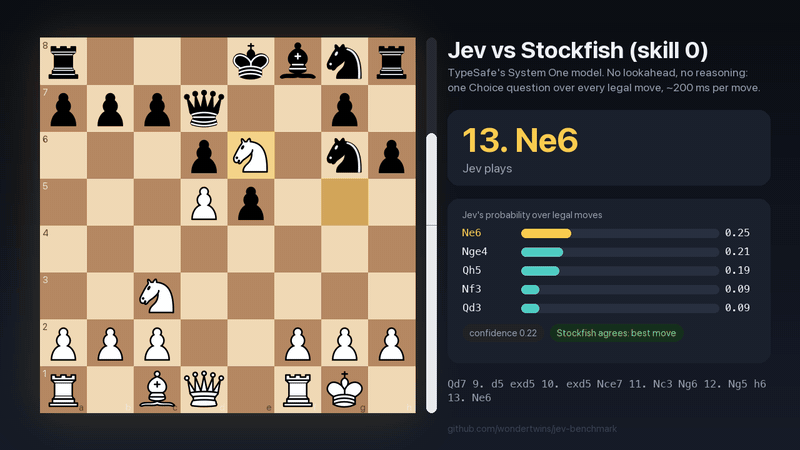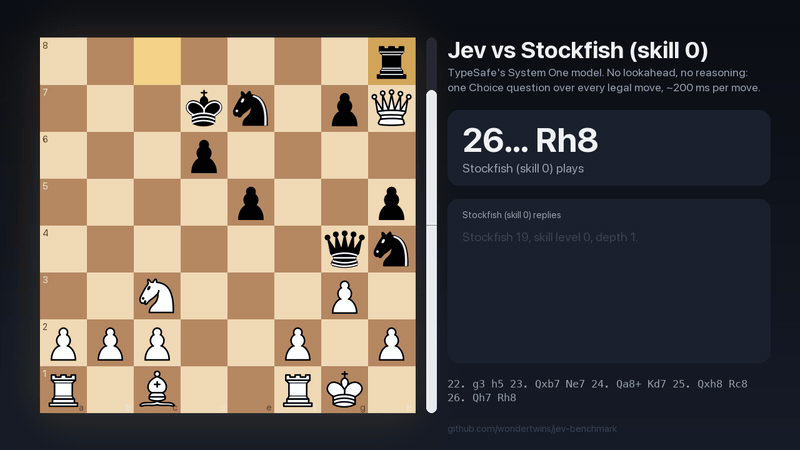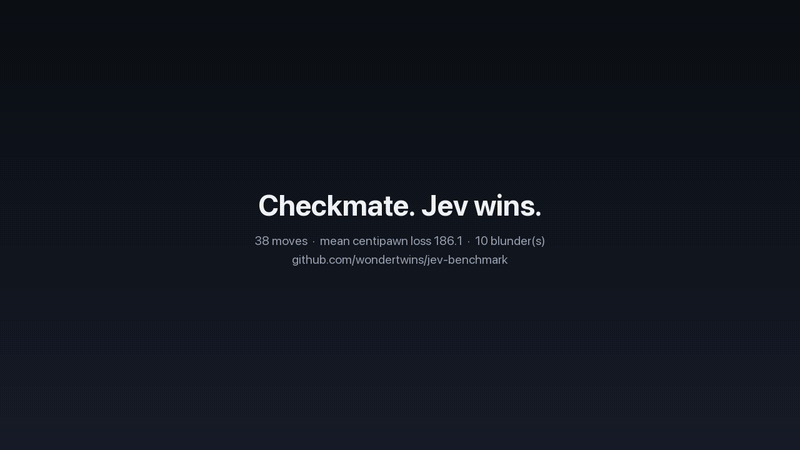
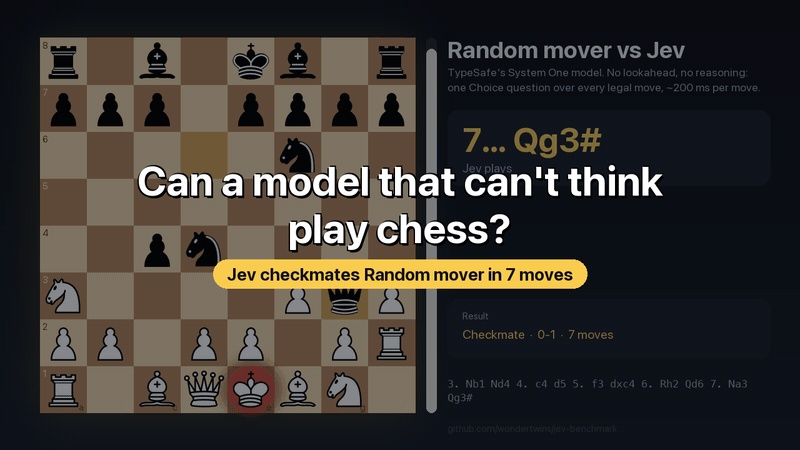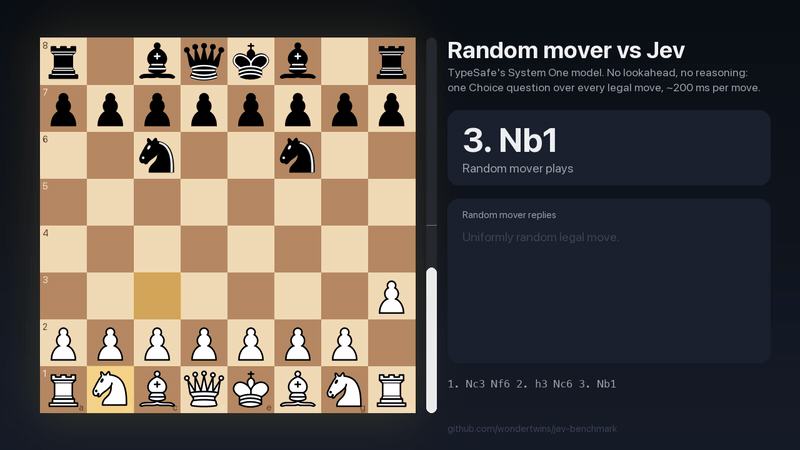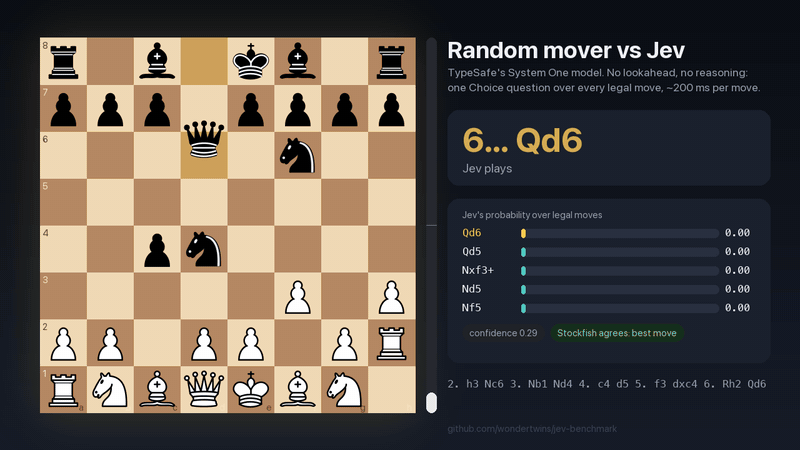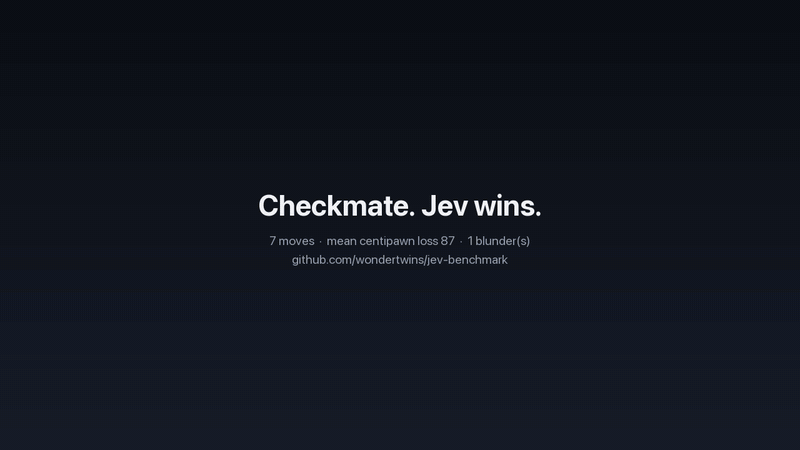
Two hands-on benchmarks of Jev , the "System One" model from TypeSafe. Jev doesn't generate text or reason step by step. You hand it state (a JSON blob) and typed questions (yes/no, pick-one, or rate-on-a-scale) and it returns calibrated probabilities in about 200 ms. The pitch is "programmable common sense": code owns the workflow, Jev supplies the judgment.
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README.