jevfire
JEV-inspired parallel decisions for CUDA LLMs. One context, many decisions. vLLM API, game-agent examples, and reproducible benchmarks.
How it uses Jev
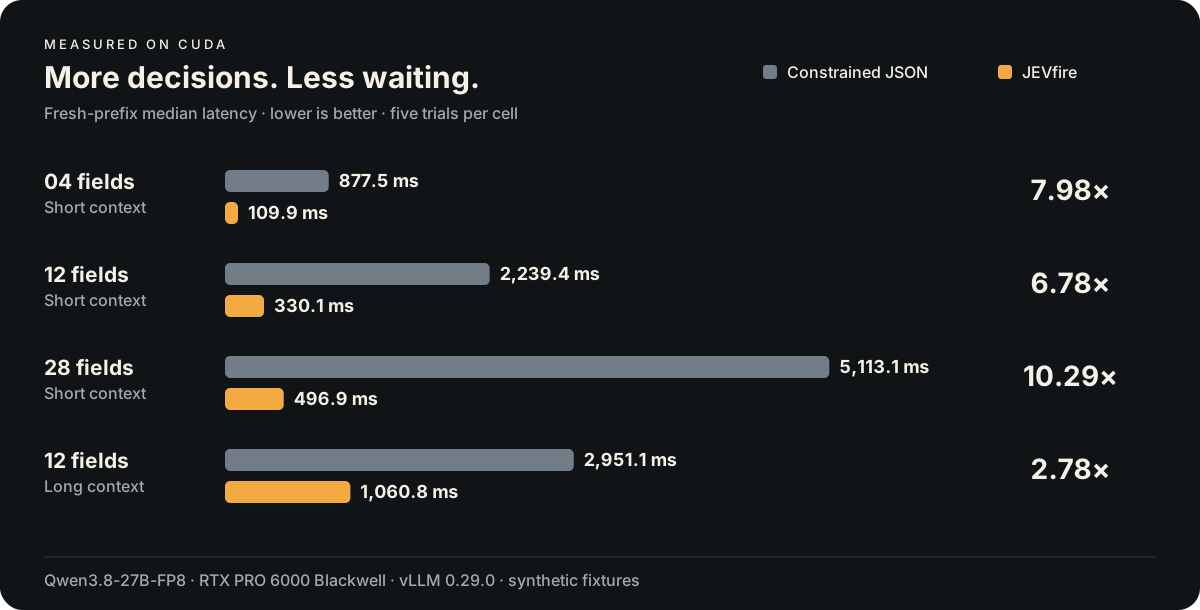
JEVfire assigns typed variables from finite choices, batching independent fields through vLLM for parallel execution and reuse of their shared instruction/context prefix when the engine cache permits it. Inspired by JEV / RLCD, it uses the pretrained model's existing language-model head to score verified single-token labels, maps the winners to allowed values, and assembles JSON in code.
Getting started
Requires Python 3.11+ and an existing compatible vLLM CUDA server. The tested backend is vLLM 0.29.0 with Qwen3.8-27B-FP8. Other models need tokenizer, template, accuracy, and performance checks. Start the tested backend →
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README · the project website.