TypeAR
Type-safe one-decision-per-token decoding engine for autoregressive LLMs, inspired by Jev.
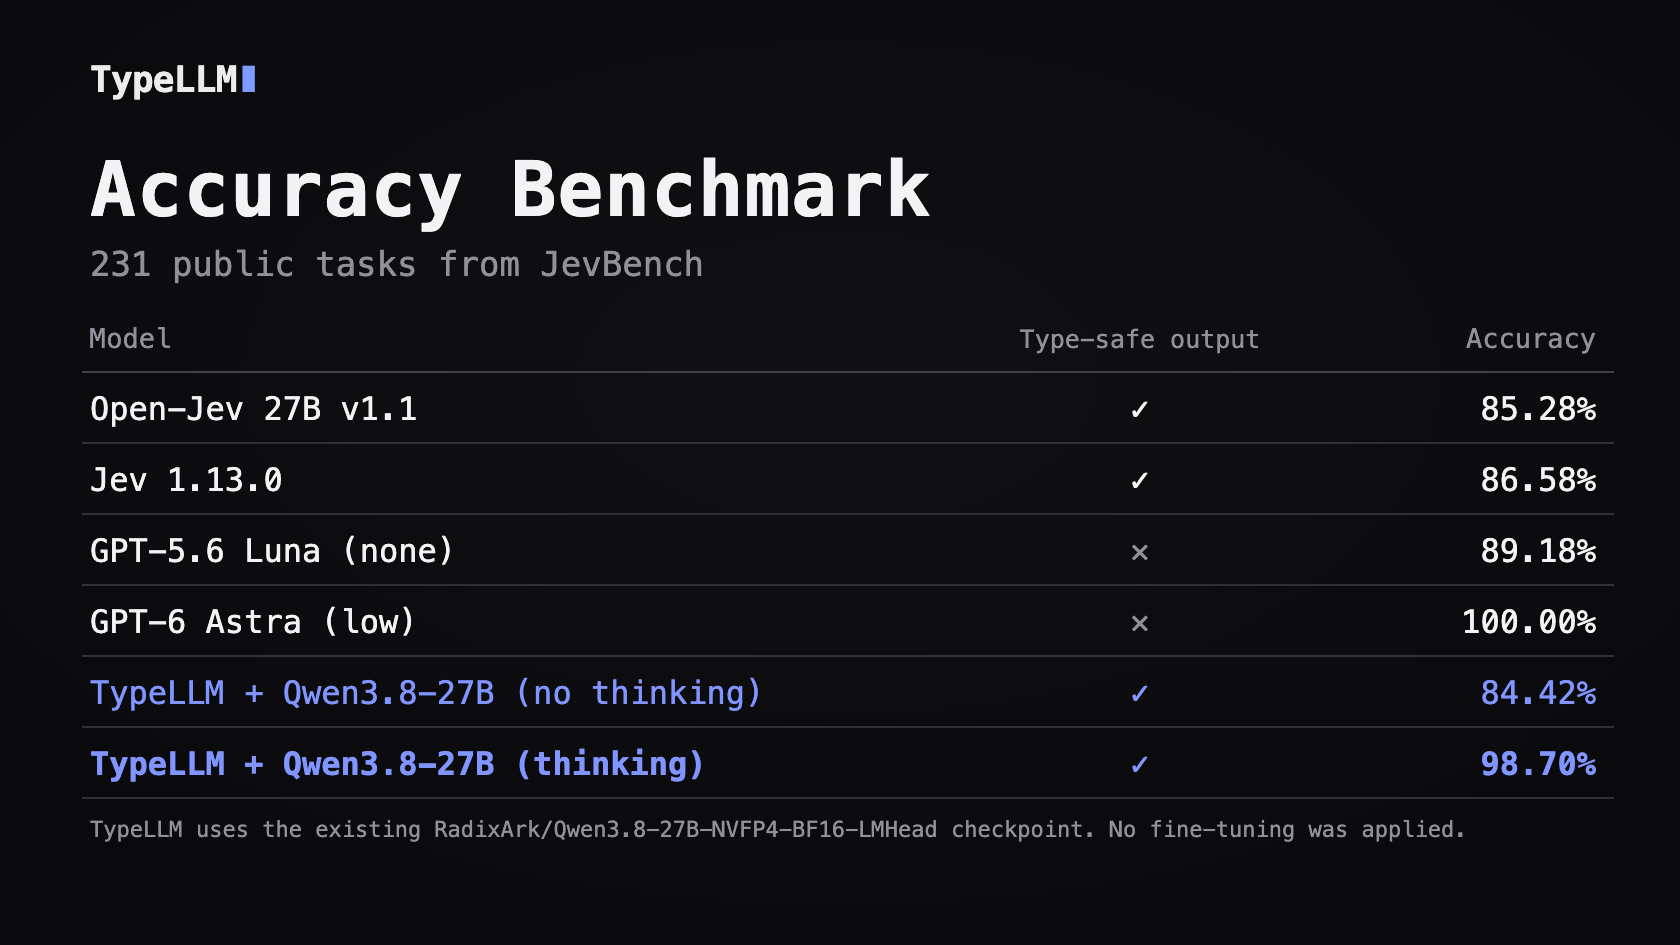
TypeLLM: LLMs with type-safe generation
How it uses Jev
TypeLLM API Self-hosted (this repo + Qwen3.8-27B) --- --- --- Classes in one choice field 512 26 Thinking speed 2.5× faster baseline Arrays of objects up to 34% higher recall, 27% faster ; 200 items a call 50 items a call Tools and human input in a workflow "source": "user" : a call pauses for your tool or a person, then resumes pass answers yourself in given OpenAI Decisions API and Jev System One compatible endpoi…
Highlights
- No out-of-schema hallucinations — Choices stay within the allowed values.
- Negligible output-token cost — Single-token categorical selection and bounded numeric decoding; optional thinking adds tokens.
- Shared-prefix reuse — KV caching avoids reprocessing shared context.
- Dependency-aware execution — Independent fields run together; declare depends on to form a dependency graph.
- Made for open autoregressive LLMs — Use compatible models you already serve with SGLang.
- Supports thinking mode — Enable reasoning before the final constrained answer.
Getting started
Call the hosted TypeLLM API, or run TypeLLM against a model you serve yourself. Both clients take the same requests.
Source: community catalog. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README · the project website.