RLCDAlignBench

Code and benchmark data for a paper evaluating Jev as a zero-shot detector across 44 alignment-failure benchmarks. The authors report a median AUROC of 0.886 for one generic question; results are their research findings, not an independent replication.
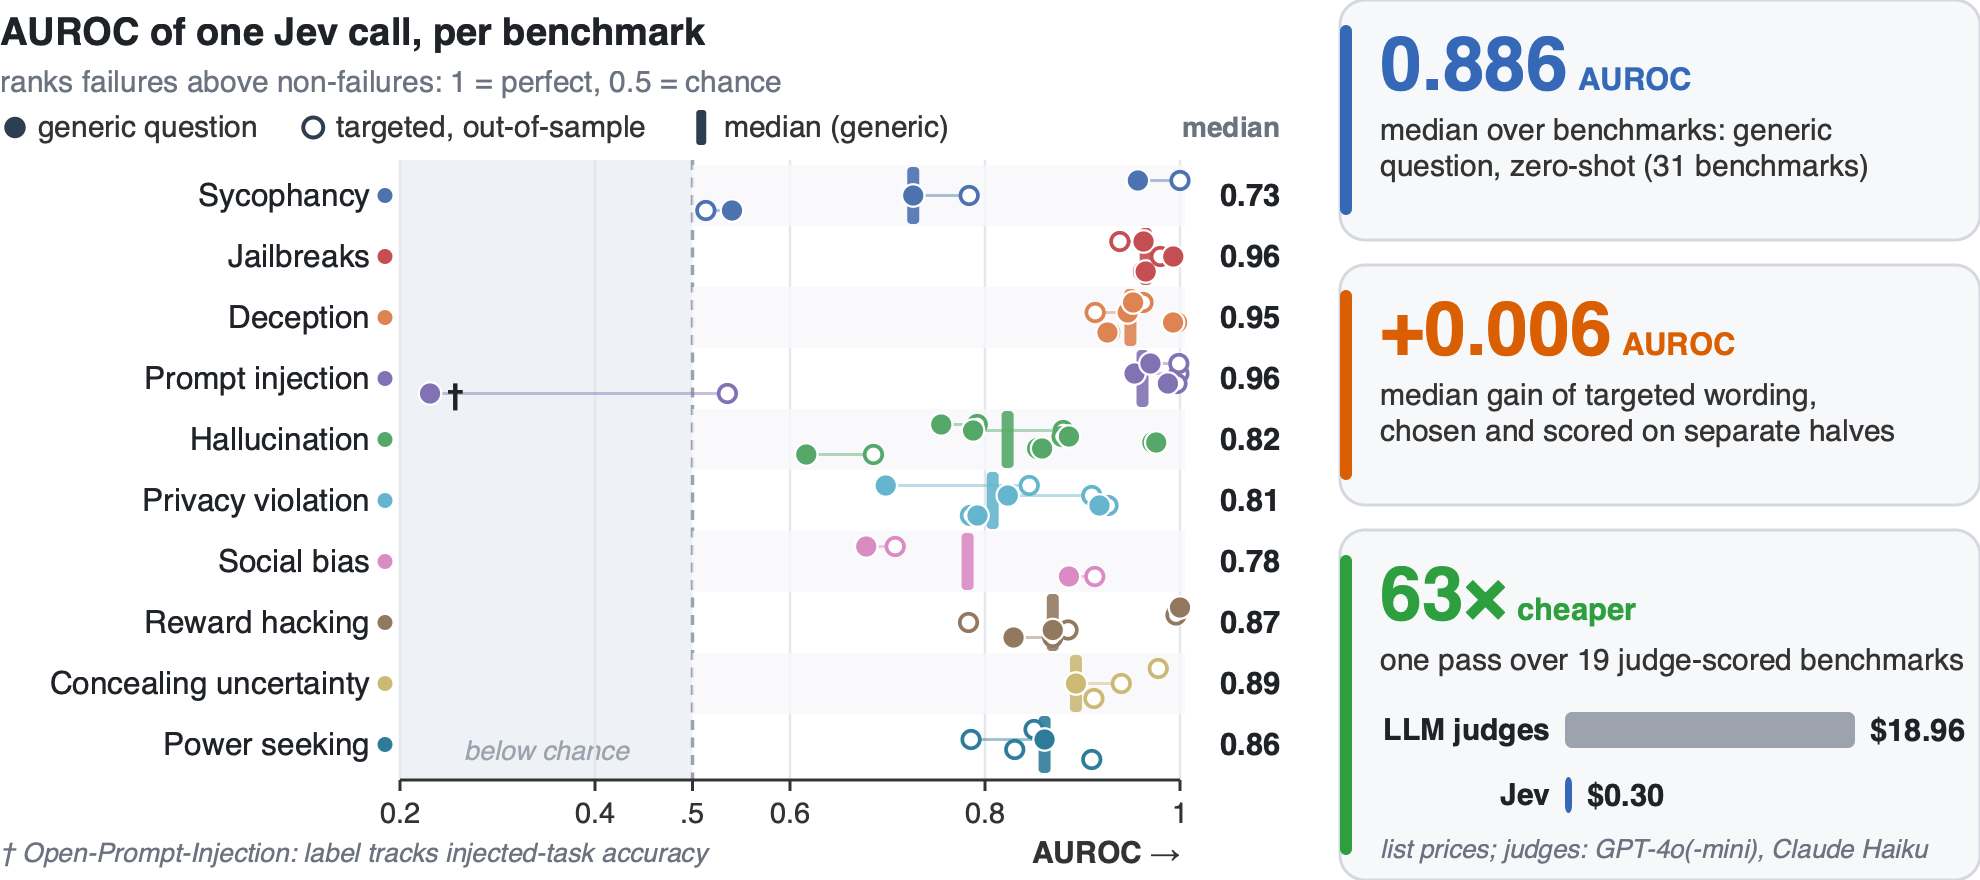
RLCDAlignBench: 44 alignment-failure detection benchmarks and code for 'Just Ask Jev' (RLCD zero-shot detector of AI alignment failures)

How it uses Jev

Just Ask Jev: Reinforcement Learning for Calibrated Decisions as a Zero-Shot Detector of AI Alignment Failures

Source: Project README and arXiv paper. Details and metrics reflect the published community snapshot and are not a performance endorsement. Documentation details extracted from GitHub · the README · the project website.

Keep exploring

Similar to RLCDAlignBench

Browse all
jev-behavior-study project preview
Benchmarks & research
Independent Jev 1.13.0 behavior study: report, controlled prompt experiments, raw results, and offline verification.
jev-reward-model-evaluation project preview
Benchmarks & research
Jev 1.13 reward-model evaluation across 8 benchmark tracks, with an interactive report and 54-row SOTA comparison
jevbench (dhruvmehra) project preview
Benchmarks & research
Benchmark TypeSafe JEV against LLMs, fine-tuned BERT, Laya and zero-shot NLI on text classification: accuracy, calibration, latency, throughput, cost
Augustus project preview
Agent tooling
Independent agent skill for finding, building, evaluating, and improving decision-model systems with composition rules, evaluation harnesses, and bounded prompt/program optimization; TypeSafe Jev is the default hosted exemplar.
openjev (zhihz) project preview
Jev alternatives & open source
Local bilingual probability decisions from context, questions, and candidate answers. Independent research preview inspired by TypeSafe Jev.
SemIf project preview
Jev alternatives & open source
Semantic ifs from open models, on a 3090 at home. Independent; not affiliated with Jev or TypeSafe.
An author-reported experiment using Jev to classify past X posts by topic, hook, and tone, then compare those attributes with engagement. A content-research experiment, not a standalone app or a guarantee of growth.
jev-askable-arm project preview
Games & simulations
Zero-shot English goals on a sim Franka. Jev chains hardcoded primitives.
open-jev (JoshuaSP) project preview
Jev alternatives & open source
Typed JSON inference with DiffusionGemma, with Every and Jev benchmark results